

unlord
Joined 12 years ago
Karma
119
Submissions
20
Member since
Apr 2
Joined 12 years ago
  nathan@arm1:~/git/rav1d.new/target$ hyperfine --warmup 2 "release/dav1d -q -i ~/Chimera-AV1-8bit-1920x1080-6736kbps.ivf -o /dev/null --threads 8"
  Benchmark 1: release/dav1d -q -i ~/Chimera-AV1-8bit-1920x1080-6736kbps.ivf -o /dev/null --threads 8
    Time (mean ± σ):     31.532 s ±  1.971 s    [User: 244.512 s, System: 1.644 s]
    Range (min … max):   28.498 s … 34.270 s    10 runs

  nathan@arm1:~/git/dav1d.new/build$ hyperfine --warmup 2 "tools/dav1d -q -i ~/Chimera-AV1-8bit-1920x1080-6736kbps.ivf -o /dev/null --threads 8"
  Benchmark 1: tools/dav1d -q -i ~/Chimera-AV1-8bit-1920x1080-6736kbps.ivf -o /dev/null --threads 8
    Time (mean ± σ):     29.696 s ±  2.308 s    [User: 230.507 s, System: 1.479 s]
    Range (min … max):   26.618 s … 35.105 s    10 runs
  nathan@arm1:~/git/rav1d.old/target$ hyperfine --warmup 2 "release/dav1d -q -i ~/Chimera-AV1-8bit-1920x1080-6736kbps.ivf -o /dev/null --threads 8"
  Benchmark 1: release/dav1d -q -i ~/Chimera-AV1-8bit-1920x1080-6736kbps.ivf -o /dev/null --threads 8
    Time (mean ± σ):     32.775 s ±  2.694 s    [User: 254.120 s, System: 1.659 s]
    Range (min … max):   28.847 s … 37.606 s    10 runs
Even if rav1d closes the gap, who will ship rav1d over dav1d? More than 85% of dav1d is hand written assembly that rav1d takes as-is and calls via unsafe blocks. Is this really memory safety?
The dav1d improvements must continuously be backported to rav1d, see the 82 closed PR's here [3]. Who is going to pay for this maintenance in perpetuity?
VideoLAN fuzzes dav1d and fixes bugs extremely quickly, typically less than 24h. The rav1d developers are Rust experts, but not codec experts. Is it reasonable to expect the same support?
[1] https://www.memorysafety.org/blog/rav1d-perf-bounty/
[2] https://github.com/memorysafety/rav1d/issues/804
[3] https://github.com/memorysafety/rav1d/pulls?q=backport+is%3A...
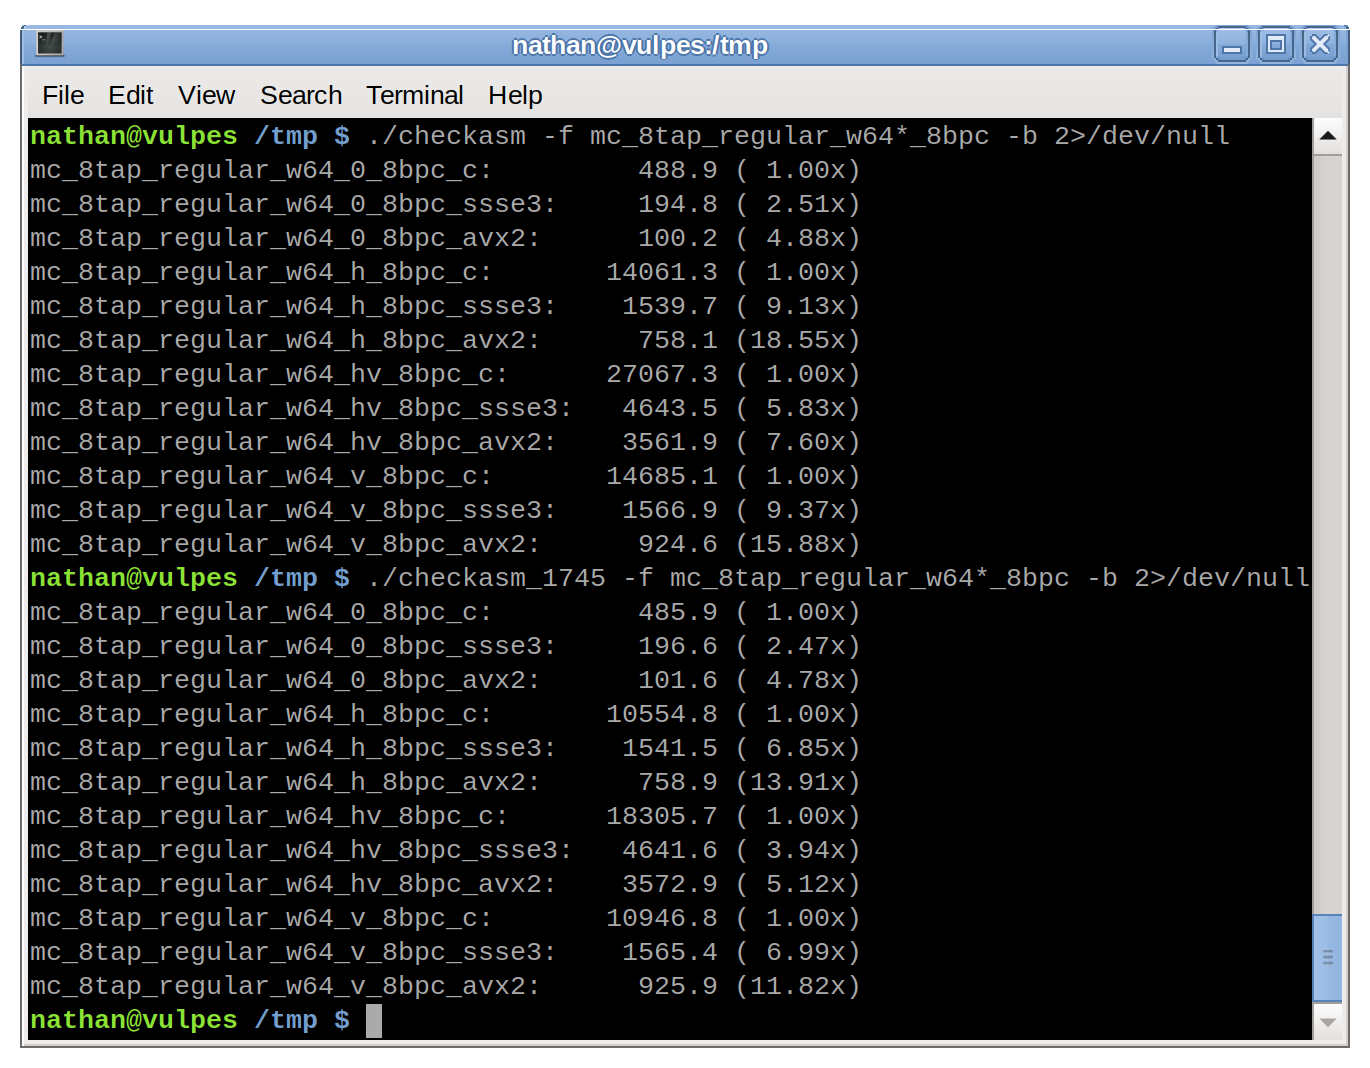
What's more, the C code is running an 8-tap filter where the SIMD for that function (in all of SSSE3, AVX2 and AVX512) is implemented as 6-tap. Last week I posted MR !1745 (https://code.videolan.org/videolan/dav1d/-/merge_requests/17...) which adds 6-tap to the C code and brings improved performance to all platforms dav1d supports.
This, of course, also closes the gap in these numbers but is a more accurate representation of the speed-up from hand-written assembly.
I agree, PSNR is a terrible measure of quality. The study "Benchmarking JPEG XL lossy/lossless image compression" (https://research.google/pubs/benchmrking-jpeg-xl-lossylossle...) which you are an author on included a controlled subjective evaluation done by EPFL using an ITU recommend methodology. The subjective results concluded:
"HEVC with SCC generally results in better rate/distortion performance when compared to JPEG XL at low bitrates (< 0.75), better preserving sharp lines and smooth areas"
It is known that AVIF performs better than HEVC. Can you say why it was not included in your 2020 subjective evaluation? It would be nice to not need to speculate on the relative quality of AVIF v JPEG XL at web bitrates.
The graph from Cloudinary uses libaom to do the encoding at speed preset 7 (aom s7), which is far from speed preset 0 and disables many AVIF coding tools. I do not know why this was chosen by the author, but it does not reflect AVIF performance. According to https://github.com/AOMediaCodec/libavif/issues/440#issuecomm... speed preset 8 loses 20-35% compression efficiency.
What features are these? You have not named a single concrete advantage. The places where AVIF out-performs JPEG XL are exactly where it make sense as an image format for the web: high fidelity images with bit rates at or below 1 bit/pixel. Nobody is browsing the web on a 16-bit panel and AVIF supports 12bpc images anyway.
Unfortunately, JPEG XL authors chose not include AVIF when they performed a subjective image comparison in 2020 under controlled viewing conditions (https://research.google/pubs/benchmarking-jpeg-xl-lossylossl...), but previous subjective studies showed AVIF outperforming PIK and FUIF over the evaluated bit-rates.
There was literally no involvement from any hardware vendor in the standardization of JPEG XL. It went from a Call for Proposals in Sept 2018 to Committee Draft in Aug 2019 with very little time for industry feedback. Contrast this with AV1 which had involvement from hardware vendors Intel, NVIDIA, Arm, AMD, Broadcom, Amlogic from the beginning as well as companies who ship media on hardware at scale such as Cisco, Netflix, Samsung and yes Google. These companies reviewed and provided significant feedback on the format that made it suitable for hardware implementation.
https://news.ycombinator.com/threads?id=JyrkiAlakuijala is a lead on the project and a Google employee, and active in JPEG XL development https://github.com/libjxl/libjxl/commits?author=jyrkialakuij...
The JPEG XL authors make claims about it's superiority over formats like AVIF, but there is no support or even timeline for hardware encode or decode on important platforms like mobile.
By contrast, Qualcomm is adding support for AV1 encoding to Snapdragon X (https://www.qualcomm.com/products/mobile/snapdragon/pcs-and-...) which could lead to efficient encoding of AVIF photos and animations.
I'm sorry this just isn't true. The K230 has RVV 1.0 hardware and has been available for 5 months.
> Which matters much less than it used to, as gcc 14 can compile C code with RVV intrinsics to either.
This is still a huge problem for fragmentation. Multimedia libraries in FFmpeg and VideoLAN use hand written assembly and only support standards compliant RVV 1.0.
There is no reason to ever produce a binary for RVV 0.7.1, it will simply fail if run on standards compliant hardware.
Note this means that animated images on the web (like GIF) are significantly smaller with AVIF than JPEG-XL which has no inter prediction.
http://jabberfr.org/tmp/ogv.js/
Note this works fine in desktop and mobile Safari.
Sure, but my comparison was to the Ittiam production decoder.
I am afraid this has not been substantiated by any of the public decoder demonstrations I've seen. Please see the most recent VVC technical update presented at the MC-IF meeting on March 2nd of this year:
https://a7dce6fd-e8f0-45f7-b0b0-255c5c9a28e1.filesusr.com/ug...
On slide 10 is a graph of VVC performance showing the VTM (VVC) decoder at 2.0x the complexity of HM (HEVC). On slide 12, the Ittiam production decoder boasts 1920x1080 @ 24fps on a 4-core Cortex A75 @ 2.5GHz.
Compare that with this recent study of dav1d (AV1) decoder complexity on a broad set of mobile SOCs, where 1920x1080 @ 24fps was easily reached by a Google Pixel 1 from 2016! Using just the two LITTLE cores! Even higher frame rates were achieved with more modern devices:
https://www.reddit.com/r/AV1/comments/gncplq/av1_multithread...
Full disclosure, I contribute to the dav1d project and performed this study.
As someone who lead an open source team (of majority volunteers) for nearly a decade at Mozilla, I can tell you that people do work on video codecs for fun, see https://github.com/xiph/daala
Working with fine people from Xiph.Org and the IETF (and later AOM) on royalty free formats Theora, Opus, Daala and AV1 was by far the most fun, interesting and fulfilling work I've had as professional engineer.