

philipkiely
Joined 8 years ago
Karma
1,210
Submissions
266
Member since
Aug 21
Joined 8 years ago
Posting this on behalf of our security team. I wanted to confirm that we collaborated with Strix on the remediation of the reported vulnerability. We thank Strix for their responsible disclosure. We took immediate steps to invalidate the leaked key and remove the public container image. Our logs confirm the vulnerability was never exploited and no customer data was exposed.
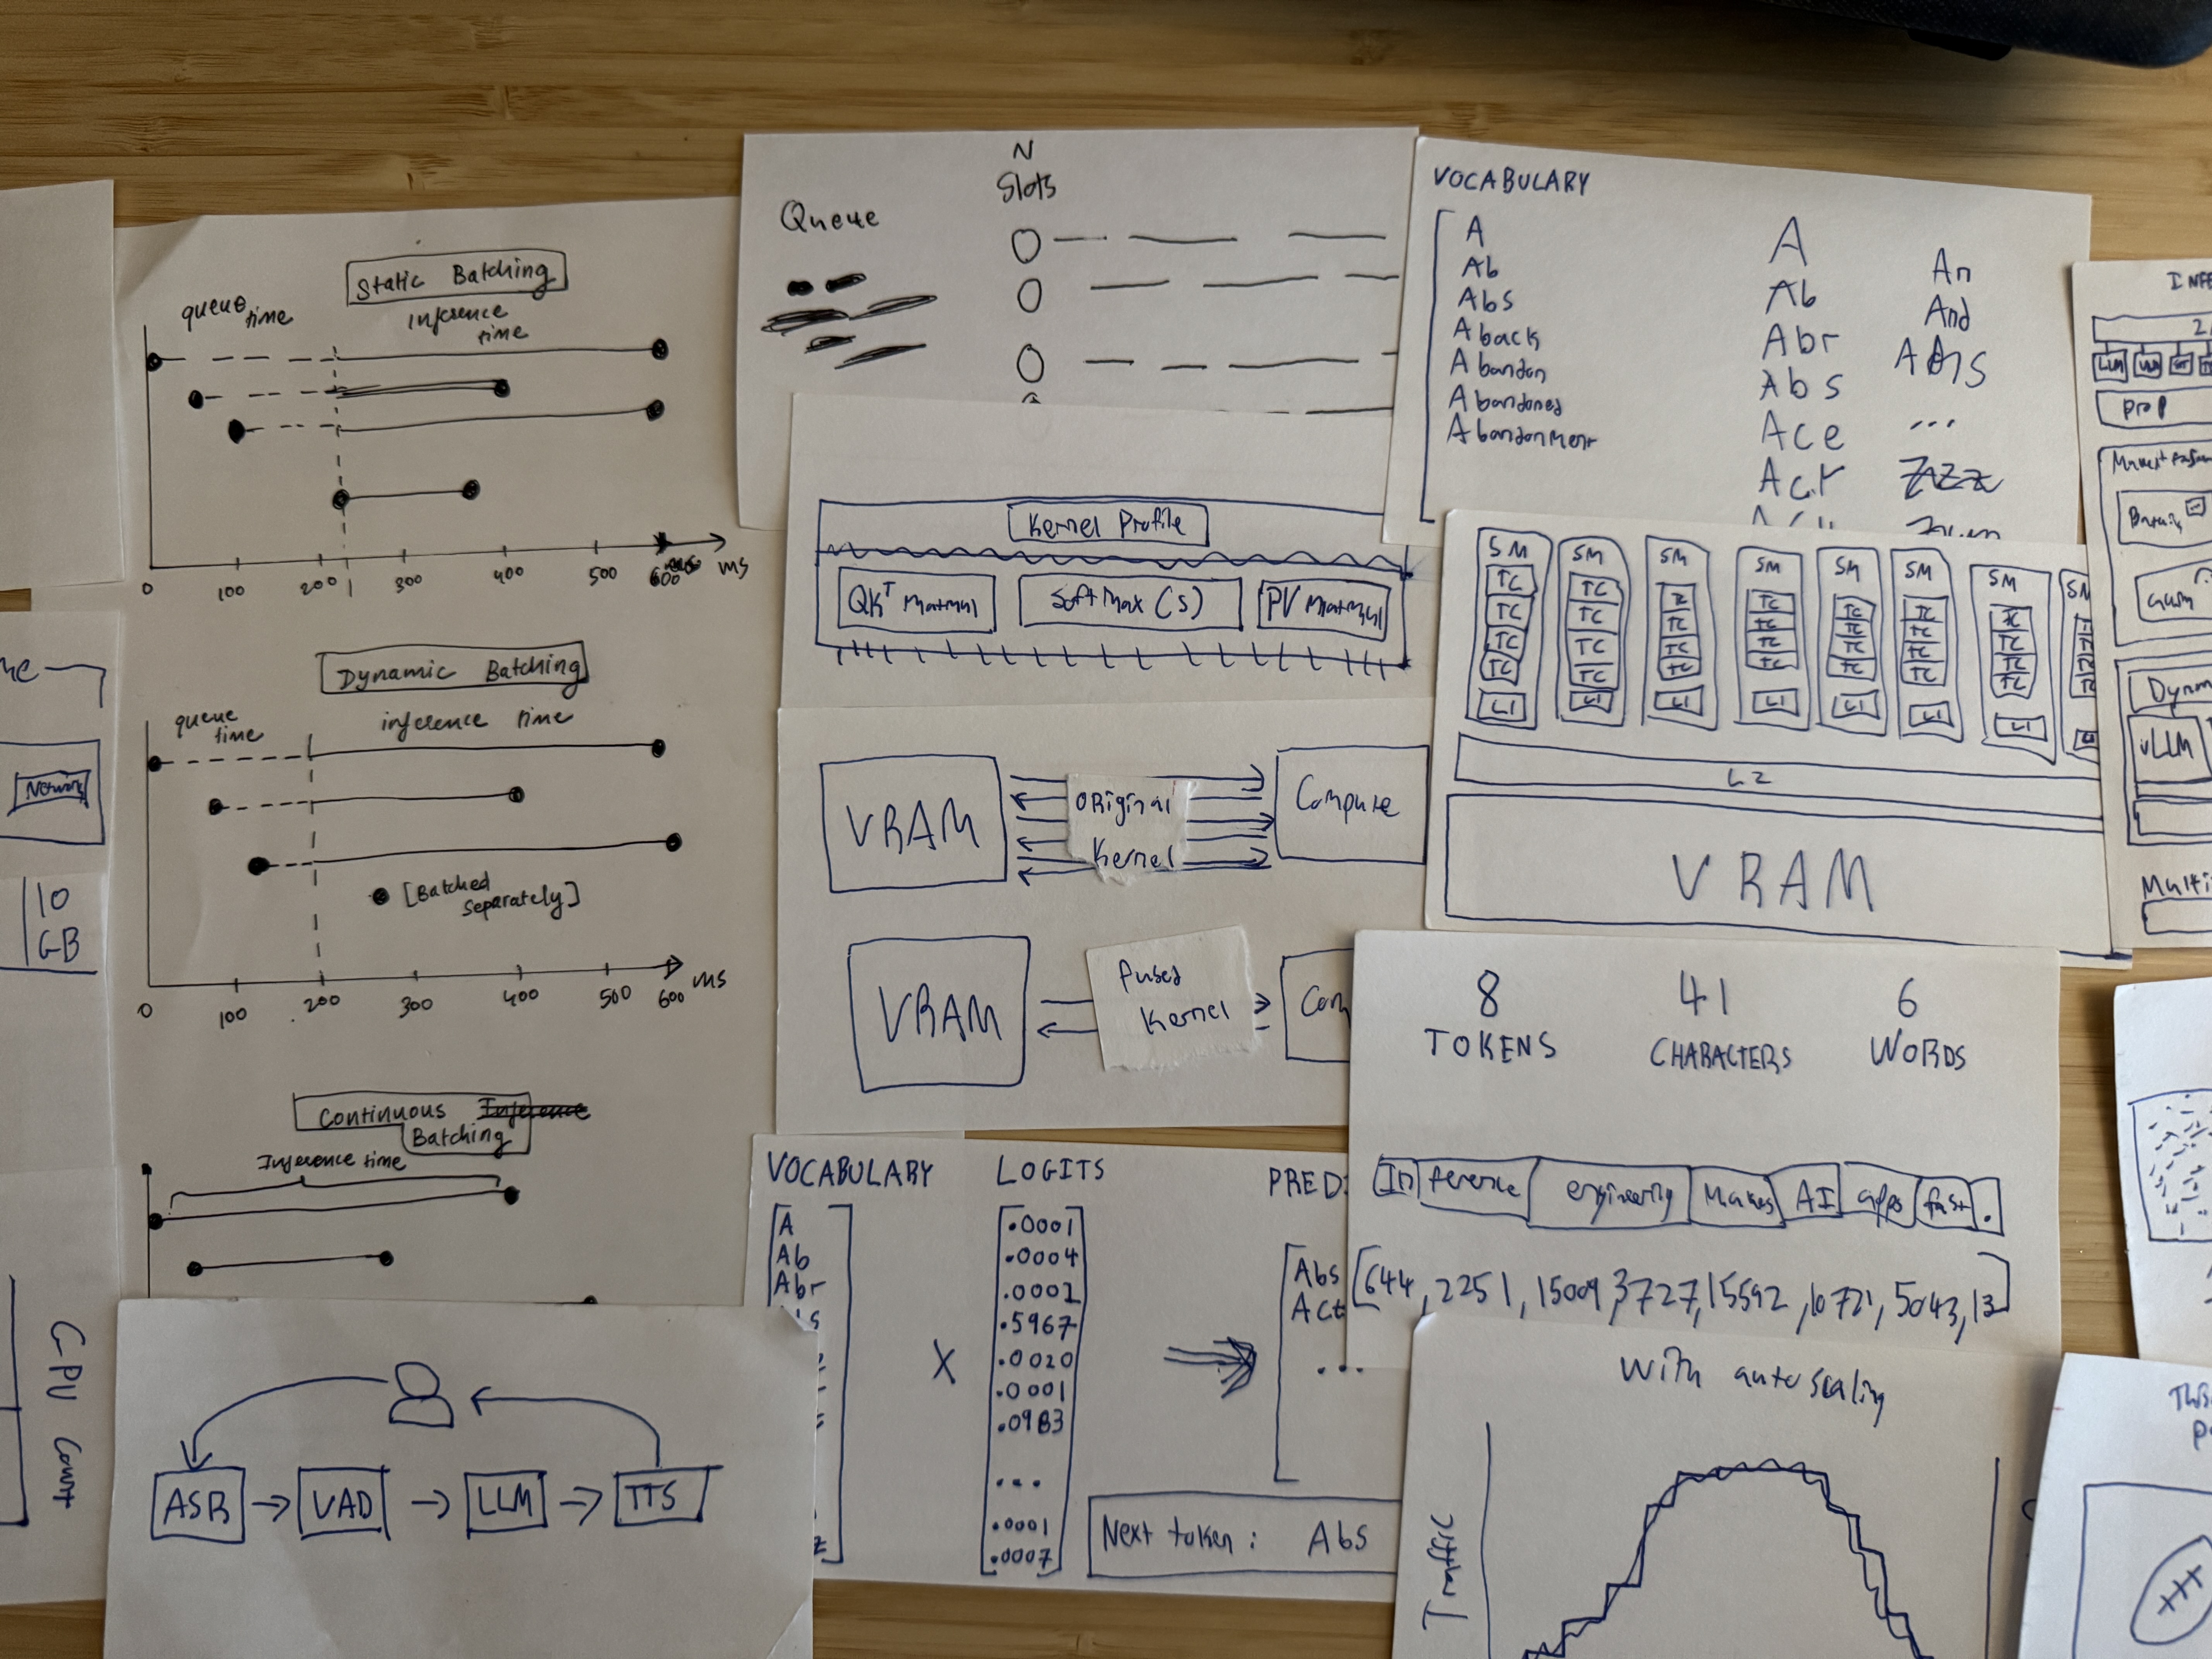
The images start out looking like this: https://philipkiely.com/images/blogs/how-to-write-a-book/des...
> In practice, the efficient frontier is very jagged. Rather than a smooth, continuous line between outcomes, small changes can have big impacts. These cutoff points are often unintuitive and must be discovered empirically through sweeps.
> However, quantization introduces a new set of tradeoffs between quality and serving efficiency. This is a particularly jagged frontier, where a large degree of improvement to serving efficiency is possible with little-to-no reduction in model quality, especially when using microscaling floating-point number formats like MXFP4 and NVFP4.
Would appreciate ideas on how to explain in greater depth
But overall yes the fundamentals of LLM performance optimization have been remarkably stable over the last few years.
Email me: username at baseten.co