binux
Joined 12 years ago
Karma
135
Submissions
14
Member since
Nov 17
Joined 12 years ago
pyspider comes from a vertical search engine project. we have two issues:
- 100+ websites, they may change the template or down sometime. We need a dashboard to monitor the changes and the fails.
- update in 5 minutes, when the website updated, we need follow that in 5 minutes. We are using a update time from index(list) page to tell the changed pages. And pages should been updated after about 30 days in case of we missed something. A powerful scheduler is needed.
obviously, I hadn't got the right way to do so with scrapy. I'm not very familiar with scrapy. So I can't say something pyspider can do but scrapy not.
But it works like a proxy, that any request with `fetch_type == 'js'` would be fetched through phantomjs and the response back to tornado_fetcher.
And yes for centralized queue which is in scheduler. It's designed to satisfy about 10-100 million urls for each project.
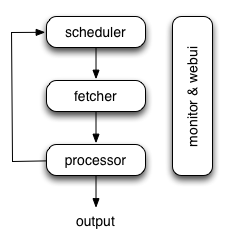
scheduler, fetchers, processors are connected with rabbitmq(alternatively). Only one scheduler is allowed. But you can run multiple fetchers or processors as needed.
There is a phantomjs fetcher that can render the page as WebKit did. Furthermore, you can have some JavaScript running before/after page loaded to simulate a mouse click.
Any advice or project that I can refer to?
pyspider is running original python code, something like portia is a code generator (Apologize if I'm wrong, I have not use it). So it can been made as another WebUI module.
But for flexible, I have no idea how to make it right currently. So, We have a css selector helper, but no plan for a complete tool.