

thangalin
Joined 17 years ago
Karma
2,920
Submissions
1,086
Member since
Oct 1
Joined 17 years ago
https://www.youtube.com/watch?v=dBnniua6-oM
Dr. Gil Carvalho (medical doctor, research scientist, science communicator) debunks parts of Lustig's 30-year-old claims:
https://www.youtube.com/watch?v=vdoDx9dIuNE
Nonetheless, Dr. Carvalho agrees with avoiding sugary drinks:
"We have a lot of recent evidence, recent studies after [Lustig's] talk. The link between soda and weight gain and obesity and other chronic diseases is quite strong."
Drink fewer sugary beverages, consume fewer calories (eat less), exercise, and drink less alcohol.
12 years with bugs, but no mammals of course.
https://www.youtube.com/watch?v=WAeHgE94rVo
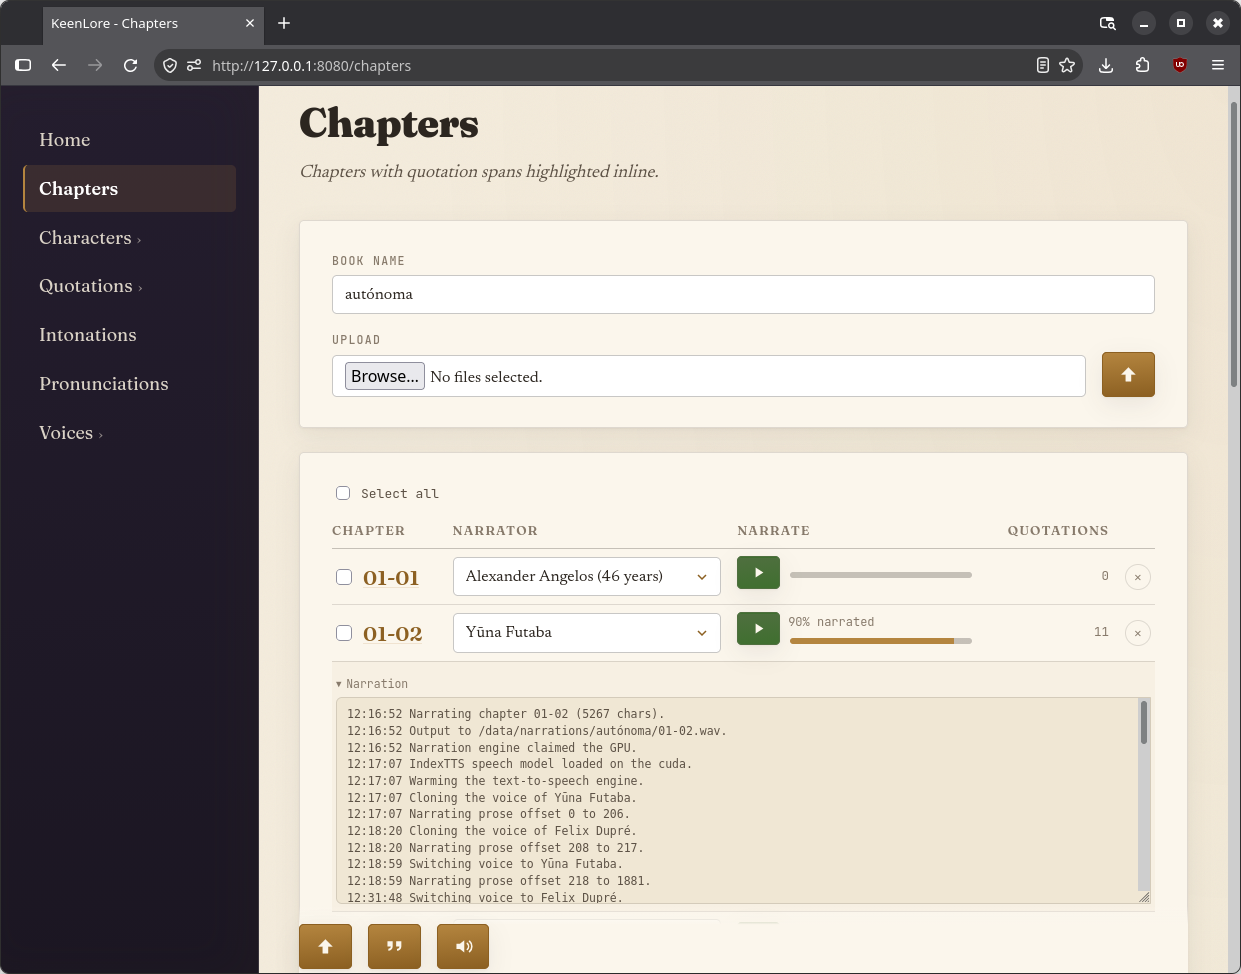
I've since added character ages (child to supercentenarian voices, consistent relative to their base adult voice), crowd chants (2 to 100 people works flawlessly), case sensitivity for character aliases (to help detect quotation attributions), custom phonetics, and English speaking characters can have a variety of accents applied. Will soon have Chatterbox driving the novel's narration. Screenshot:
https://i.ibb.co/GffgfnCL/narrating.png
It's self-hosted, fully local, based on software having permissive licenses and open weights. Runs on a lowly 8GB NVIDIA T1000 (and 96 GB of RAM).
Sealed terrariums? Unless you mean something more complex than plants, soil, sunlight, and water?
https://laidbackgardener.blog/2019/10/14/the-worlds-second-o...
"That means it has been growing inside its bottle with no additional air, water or fertilizer for 47 years."
KeenLore is my locally hosted full-cast emotive audiobook generator I'm developing for my novel:
https://www.youtube.com/watch?v=WAeHgE94rVo
Another HN user suggested embedding sound effects. The lead author of MOSS-TTS emailed me that the next version will have a SOTA voice designer. Poke around the voice design space, you'll find text-to-effects here and there. I certainly have my eyes on this space.
Guilty.
> I profoundly disagree
People will take to wearing corrective contact lenses that will have recording capabilities in a few years. This is going to open up a huge can of worms for privacy, cinemas, and more. I did not write that we mustn't do anything about it right now, only that it is short-sighted. Creating laws about wearable recording devices would benefit from addressing near-future technology, which will include easily concealed digitally augmented corrective lenses.
* https://www.regjeringen.no/no/aktuelt/vil-innfore-midlertidi...
* https://www.regjeringen.no/en/dep/dfd/org/minister-of-digita...
* Contact: [email protected]
https://www.youtube.com/watch?v=WAeHgE94rVo
The system performs quotation attribution on my local hardware for my near-future, hard sci-fi novel (having nearly 500 quotations) with over 97% accuracy.
The initial prototype was developed quite quickly, but numerous successive iterations were required to fix numerous gaffs by Opus 5 (because it doesn't actually _understand_ what it takes to make general-purpose audiobook narration software).
I'm running Arch Linux and would rather not install DaVinci Resolve, but Blender would be fine for the non-linear video editor.
My plan is to use ChatCut to trim and split into the different sections. After I have the five segments, what would you suggest for swapping the background (environment) and attire? There are two simultaneous camera shots (front and side) that I'd like to stitch together as well.
Any suggestions? (Paying someone a couple of hundred $CAD to take this task off my plate would also work.)
I wasn't able to find a version of these that can create voice samples based on voice designs. Do you mean to use Qwen3 TTS Voice Design to create samples followed by Higgs or Fish Audio to clone the sample voices and narrate the novel?
MOSS-TTS 2.0 will apparently have voice design, as well, on par with ElevenLabs quality.
Good idea, not something I've considered yet. Wouldn't take much to add it since there's already a feature for selecting a quotation and assigning it an intonation. Same infrastructure could be reused to select arbitrary text and assign stage directions.
https://www.youtube.com/watch?v=WAeHgE94rVo
No cloud, no tokens to pay. Reads a book using a full cast of characters. Quotation attribution detection (for my novel) is at 97.2% accuracy (485/499 quotes identified and assigned correctly). The autofill of character voice descriptions uses the prose to determine how the character sounds.
Employs Gemma 4[1] for the prose analysis (voice fills, quotation detection) and Qwen3 TTS Voice Design[2] for creating voice samples. Runs on an 8GB NVIDIA T1000 GPU card, 96 GB RAM, and a AMD Ryzen 5 7600.
[1]: https://deepmind.google/models/gemma/gemma-4/
[2]: https://huggingface.co/spaces/Qwen/Qwen3-TTS-Voice-Design
https://en.wikipedia.org/wiki/Kodkod#/media/File:Leopardus_g...


username @ gmail