namnnumbr
Joined 5 years ago
Karma
290
Submissions
33
Member since
Nov 16
Joined 5 years ago
1. GPUs create heat. There's no efficient way to get rid of the heat in space (vacuum is an insulator). 2. Die-shrink makes modern processors and memory more and more susceptible to radiation; shielding is possible, but adds cost + mass (which adds cost)
Also (shameless self-promo) I publish a 2x weekly blog just to force myself to keep up: https://aimlbling-about.ninerealmlabs.com/treadmill/
If you can forgive the obviously-AI-generated writing, [CPUs Aren't Dead](https://seqpu.com/CPUsArentDead) makes an interesting point on AI progress: Google's latest, smallest Gemma model (Gemma 4 E2B), which can run on a cell phone, outperforms GPT-3.5-turbo. Granted, this factoid is based on `MT-Bench` performance, a benchmark from 2023 which I assume to be both fully saturated and leaked into the training data for modern LLMs. However, cross-referencing [Artificial Analysis' Intelligence Index](https://artificialanalysis.ai/models?models=gemma-4-e2b-non-...) suggests that indeed the latest 2B open-weights models are capable of matching or beating 175B models from 3-4 years ago. Perhaps more impressive, [Gemma 4 E4B matches or beats GPT-4o](https://artificialanalysis.ai/models?models=gemma-4-e4b%2Cge...) on many benchmarks.
If this trend continues, perhaps we'll have the capabilities of today's best models available to reasonably run on our laptops!
1. In my own use, since 1 Apr this month, very heavy coding:
> 472.8K Input Tokens +299.3M cached > 2.2M Output Tokens
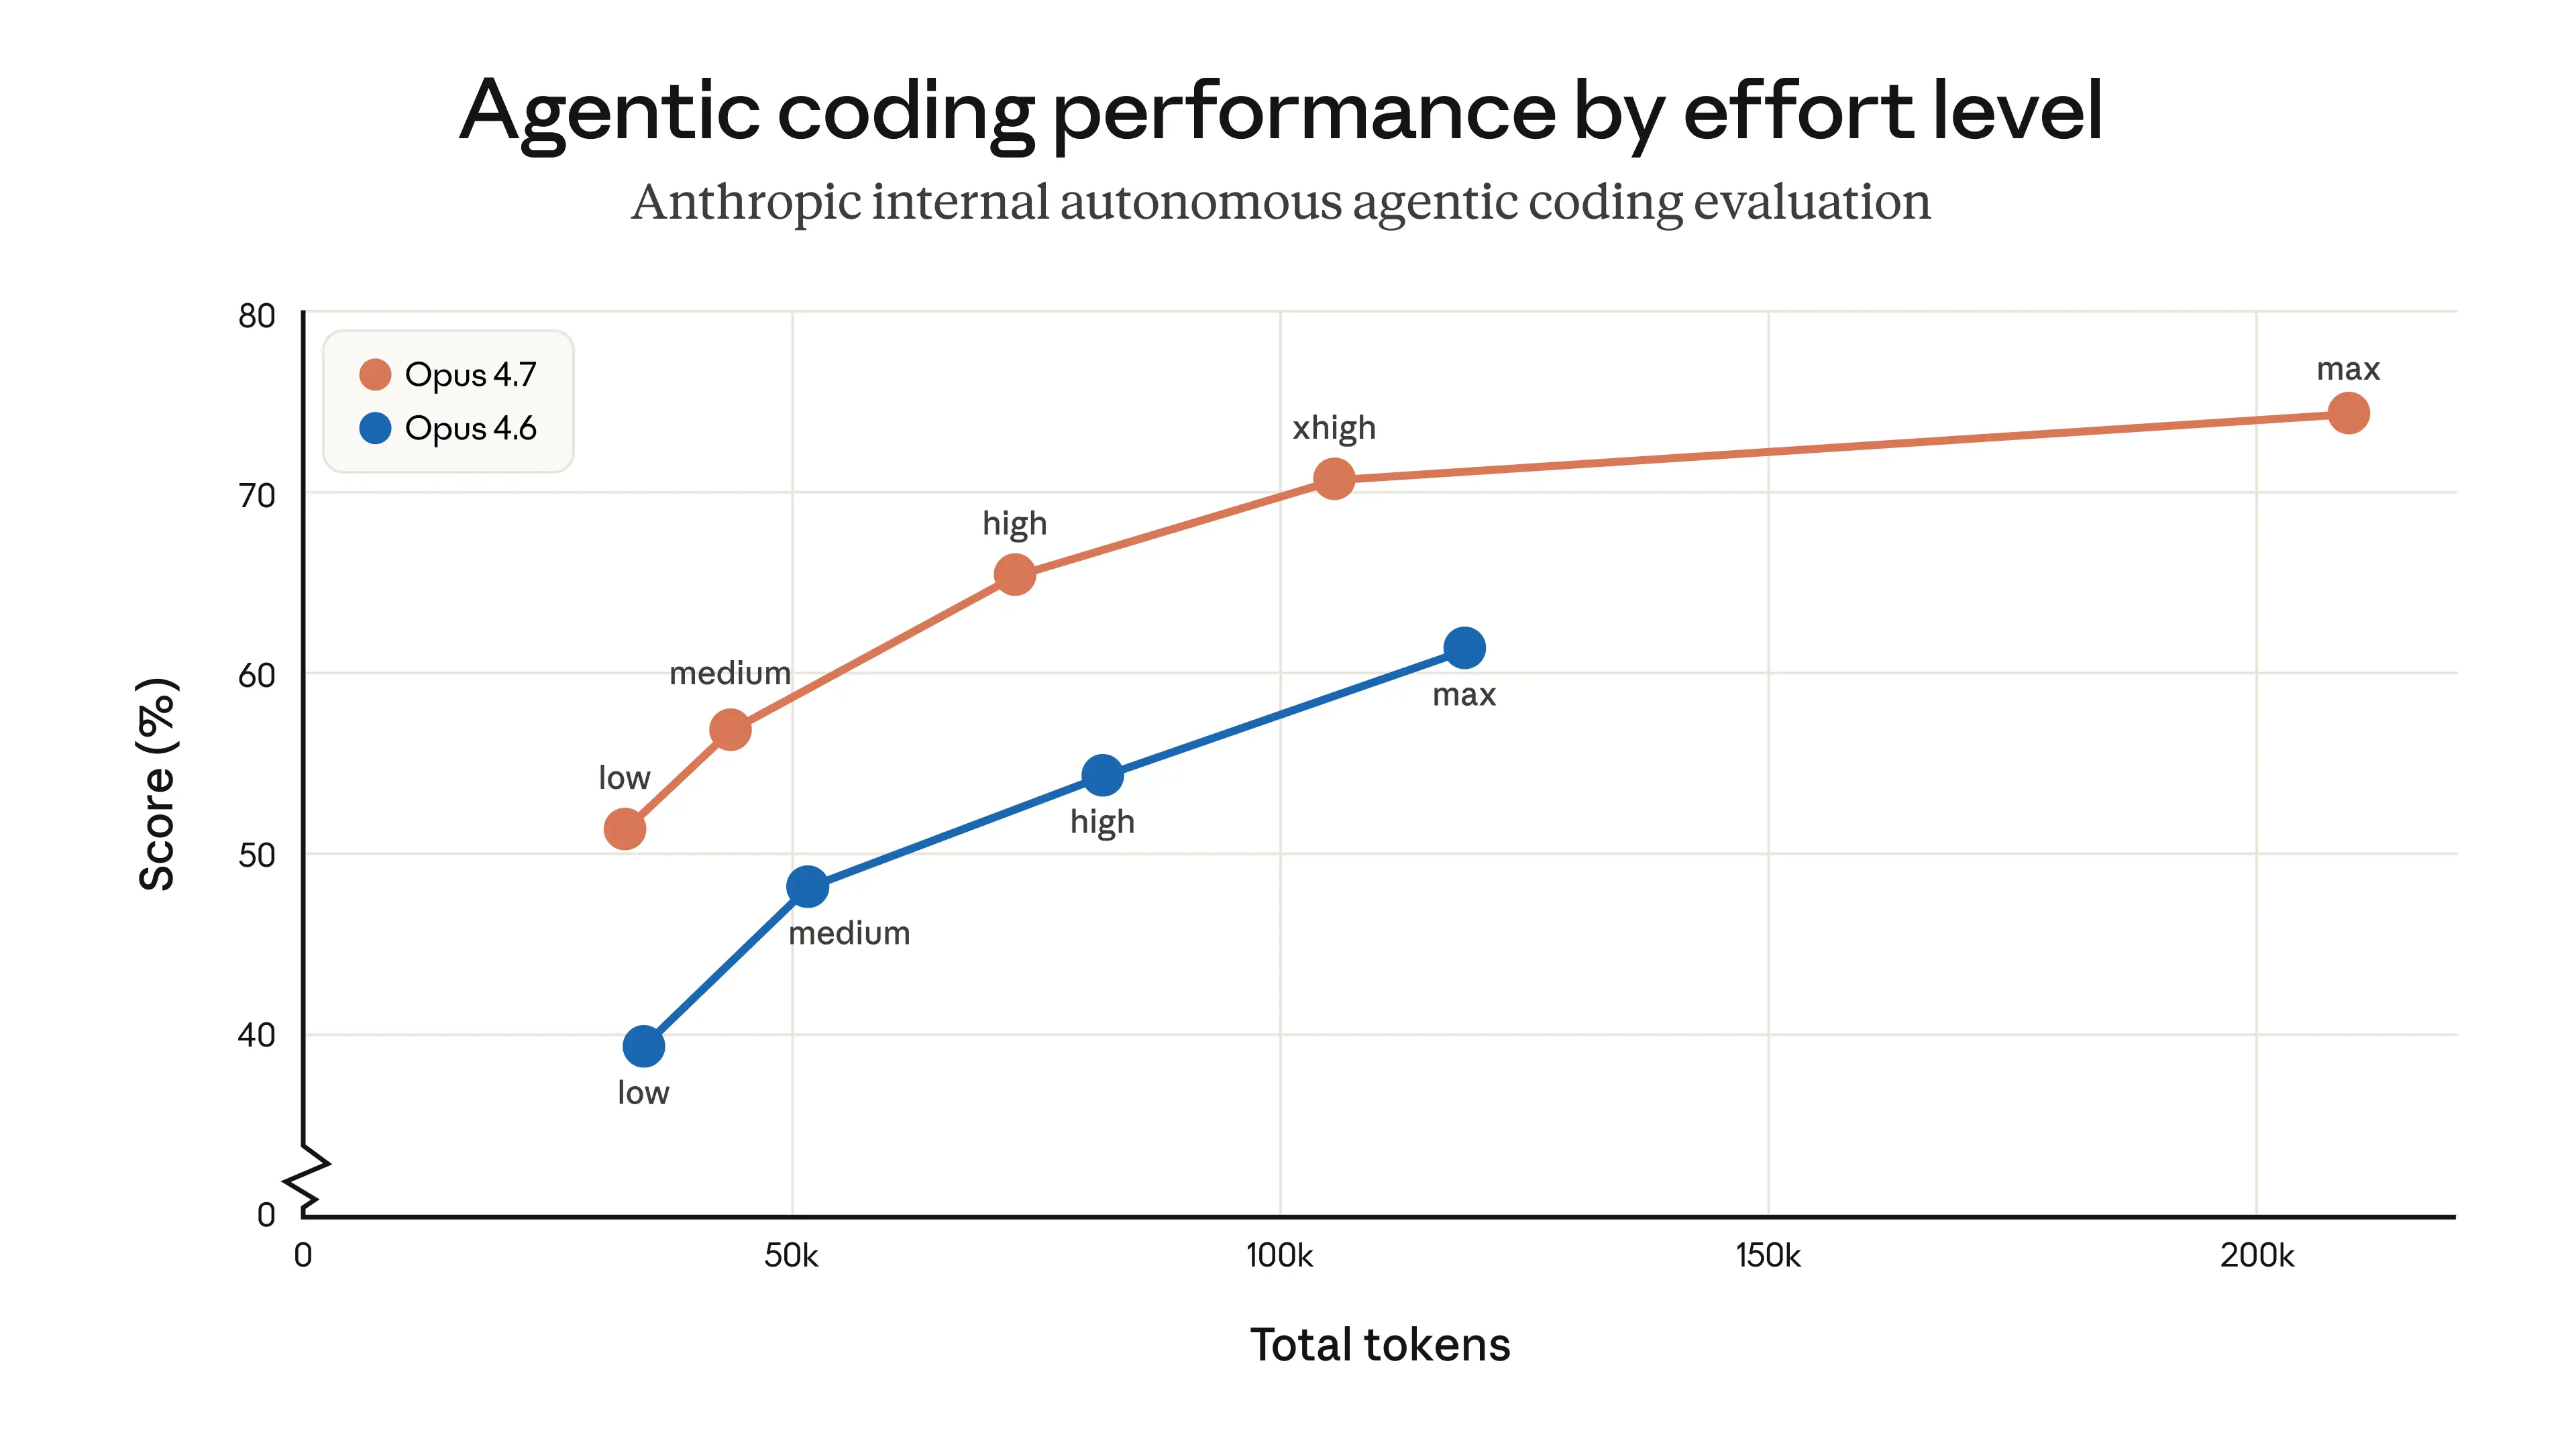
My workloads generate ~5x more output than input, and output tokens cost 5x more per token... output dominates my bill at roughly 25x the cost of input. (Even more so when you consider cache hits!) If Opus 4.7 was more efficient with reasoning (and thus output), I'd likely save considerable money (were I paying per-token).
2. Anthropic's benchmarks DO show strictly-better (granted they are Anthropic's benchmarks, so salt may be needed) https://www.anthropic.com/_next/image?url=https%3A%2F%2Fwww-...
https://www.anthropic.com/_next/image?url=https%3A%2F%2Fwww-...
The final calculation assumes that Opus 4.7 uses the exact same trajectory + reasoning output as Opus 4.6. I have not verified, but I assume it not to be the case, given that Opus 4.7 on Low thinking is strictly better than Opus 4.6 on Medium, etc., etc.
Happy to take suggestions on this!
However, the essay and the guidelines were all human-written!