nabakin
Joined 9 years ago
Karma
2,189
Submissions
668
Member since
Dec 6
Joined 9 years ago
That is a huge claim to make with no evidence.
I researched what you said, and I have found no statement to that effect in their paper[0], on huggingface[1], twitter[2], WeChat[3], or in their news release[4].
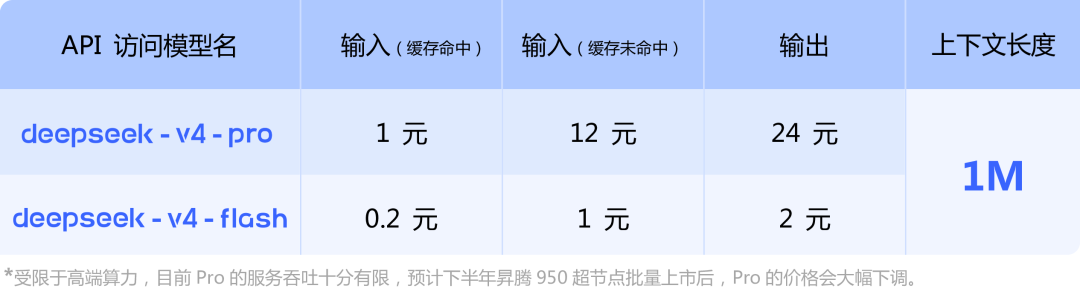
They only mention as a footnote in only the Chinese version of their news release that they plan to reduce inference costs with the Ascend 950 supernode when it releases[5]. The only mention of Huawei in their paper is that they validated a technique to lower interconnect bandwidth on Ascend NPUs and Nvidia GPUs[6].
[0] https://huggingface.co/deepseek-ai/DeepSeek-V4-Pro/blob/main...
[1] https://huggingface.co/deepseek-ai/DeepSeek-V4-Pro
[2] https://xcancel.com/deepseek_ai/status/2047516922263285776
[3] https://mp.weixin.qq.com/s/8bxXqS2R8Fx5-1TLDBiEDg
[4] https://api-docs.deepseek.com/news/news260424
[5] https://api-docs.deepseek.com/zh-cn/img/v4-price.png
[6] Page 16
Electrons themselves don't move at the speed of light, but information transfer (i.e. communication) via electrons does happen close to the speed of light.
A subtle, but important, distinction that's often misunderstood and means computational performance gains would probably come from bandwidth, not latency.
Looking around, SWE Rebench seems to have decent protection against training data leaks[1]. Kagi has one that is fully private[2]. One on HuggingFace that claims to be fully private[3]. SimpleBench[4]. HLE has a private test set apparently[5]. LiveBench[6]. Scale has some private benchmarks but not a lot of models tested[7]. vals.ai[8]. FrontierMath[9]. Terminal Bench Pro[10]. AA-Omniscience[11].
So I guess we do have some decent private benchmarks out there.
[0] https://arcprize.org/leaderboard
[1] https://swe-rebench.com/about
[2] https://help.kagi.com/kagi/ai/llm-benchmark.html
[3] https://huggingface.co/spaces/DontPlanToEnd/UGI-Leaderboard
[7] https://labs.scale.com/leaderboard
[9] https://epoch.ai/frontiermath/
[10] https://github.com/alibaba/terminal-bench-pro
[11] https://artificialanalysis.ai/articles/aa-omniscience-knowle...
I agree it's misleading for them to hyper-focus on one metric, but public benchmarks are far from the only thing that matters. I place more weight on Lmarena scores and private benchmarks.