

make3

Joined 13 years ago

Karma
1,911
Submissions
2,240
Member since
Apr 15
FFEEDD ff6600 a77858
View on Hacker News

Recent submissions

Comment · 2 days ago
Training neural networks is requires extremely high speed interconnect between the humongous GPUs
Comment · 2 days ago
I'm not sure we played the same game
Comment · 2 days ago
the depth comes from the character stories and development, like Laezel and Shadowheart
Comment · 4 days ago
personally I think it's because of models trained so hard to be good at Math and Coding with reinforcement learning, which makes them kind of crazy hard reasoners, and bad for casual discussion
Comment · 10 days ago
maybe obvious, but Baldur's Gate 3 is really that level (or better) of a game (recommendation)
Comment · 18 days ago
The models are solving Millennium Prize questions and making progress on the Riemann Hypothesis, yet the top comment is still looking at pelicans somehow. To me, it feels even more superficial and pointless than arguing about the presidential candidates' tie choices in a debate.
Comment · 19 days ago
> "Python used to have limited parallelism, due to its global interpreter lock (GIL). Only one thread could run Python code at a time.”

It is still limited this way in the regular build, there's no "used to". Author should fix that.

Comment · 19 days ago
Importantly though, LLMs can generate questions in parallel, and there can be much fewer questions (q) than segments to evaluate against (n), so the cost of jev on questions (jev(q * n) + llm(q)) vs the cost of putting all the segments in the LLM can be smaller (llm(n)), (llm(n) >> llm(q) + jev(n * q) if n >> q)

The real benchmark that's missing for me is MaxSim on a real embedder from MTEB.

Comment · 20 days ago
People are allowed to defend themselves man. In this case, economic pressure is the only thing that's likely to work medium term.
Comment · 21 days ago
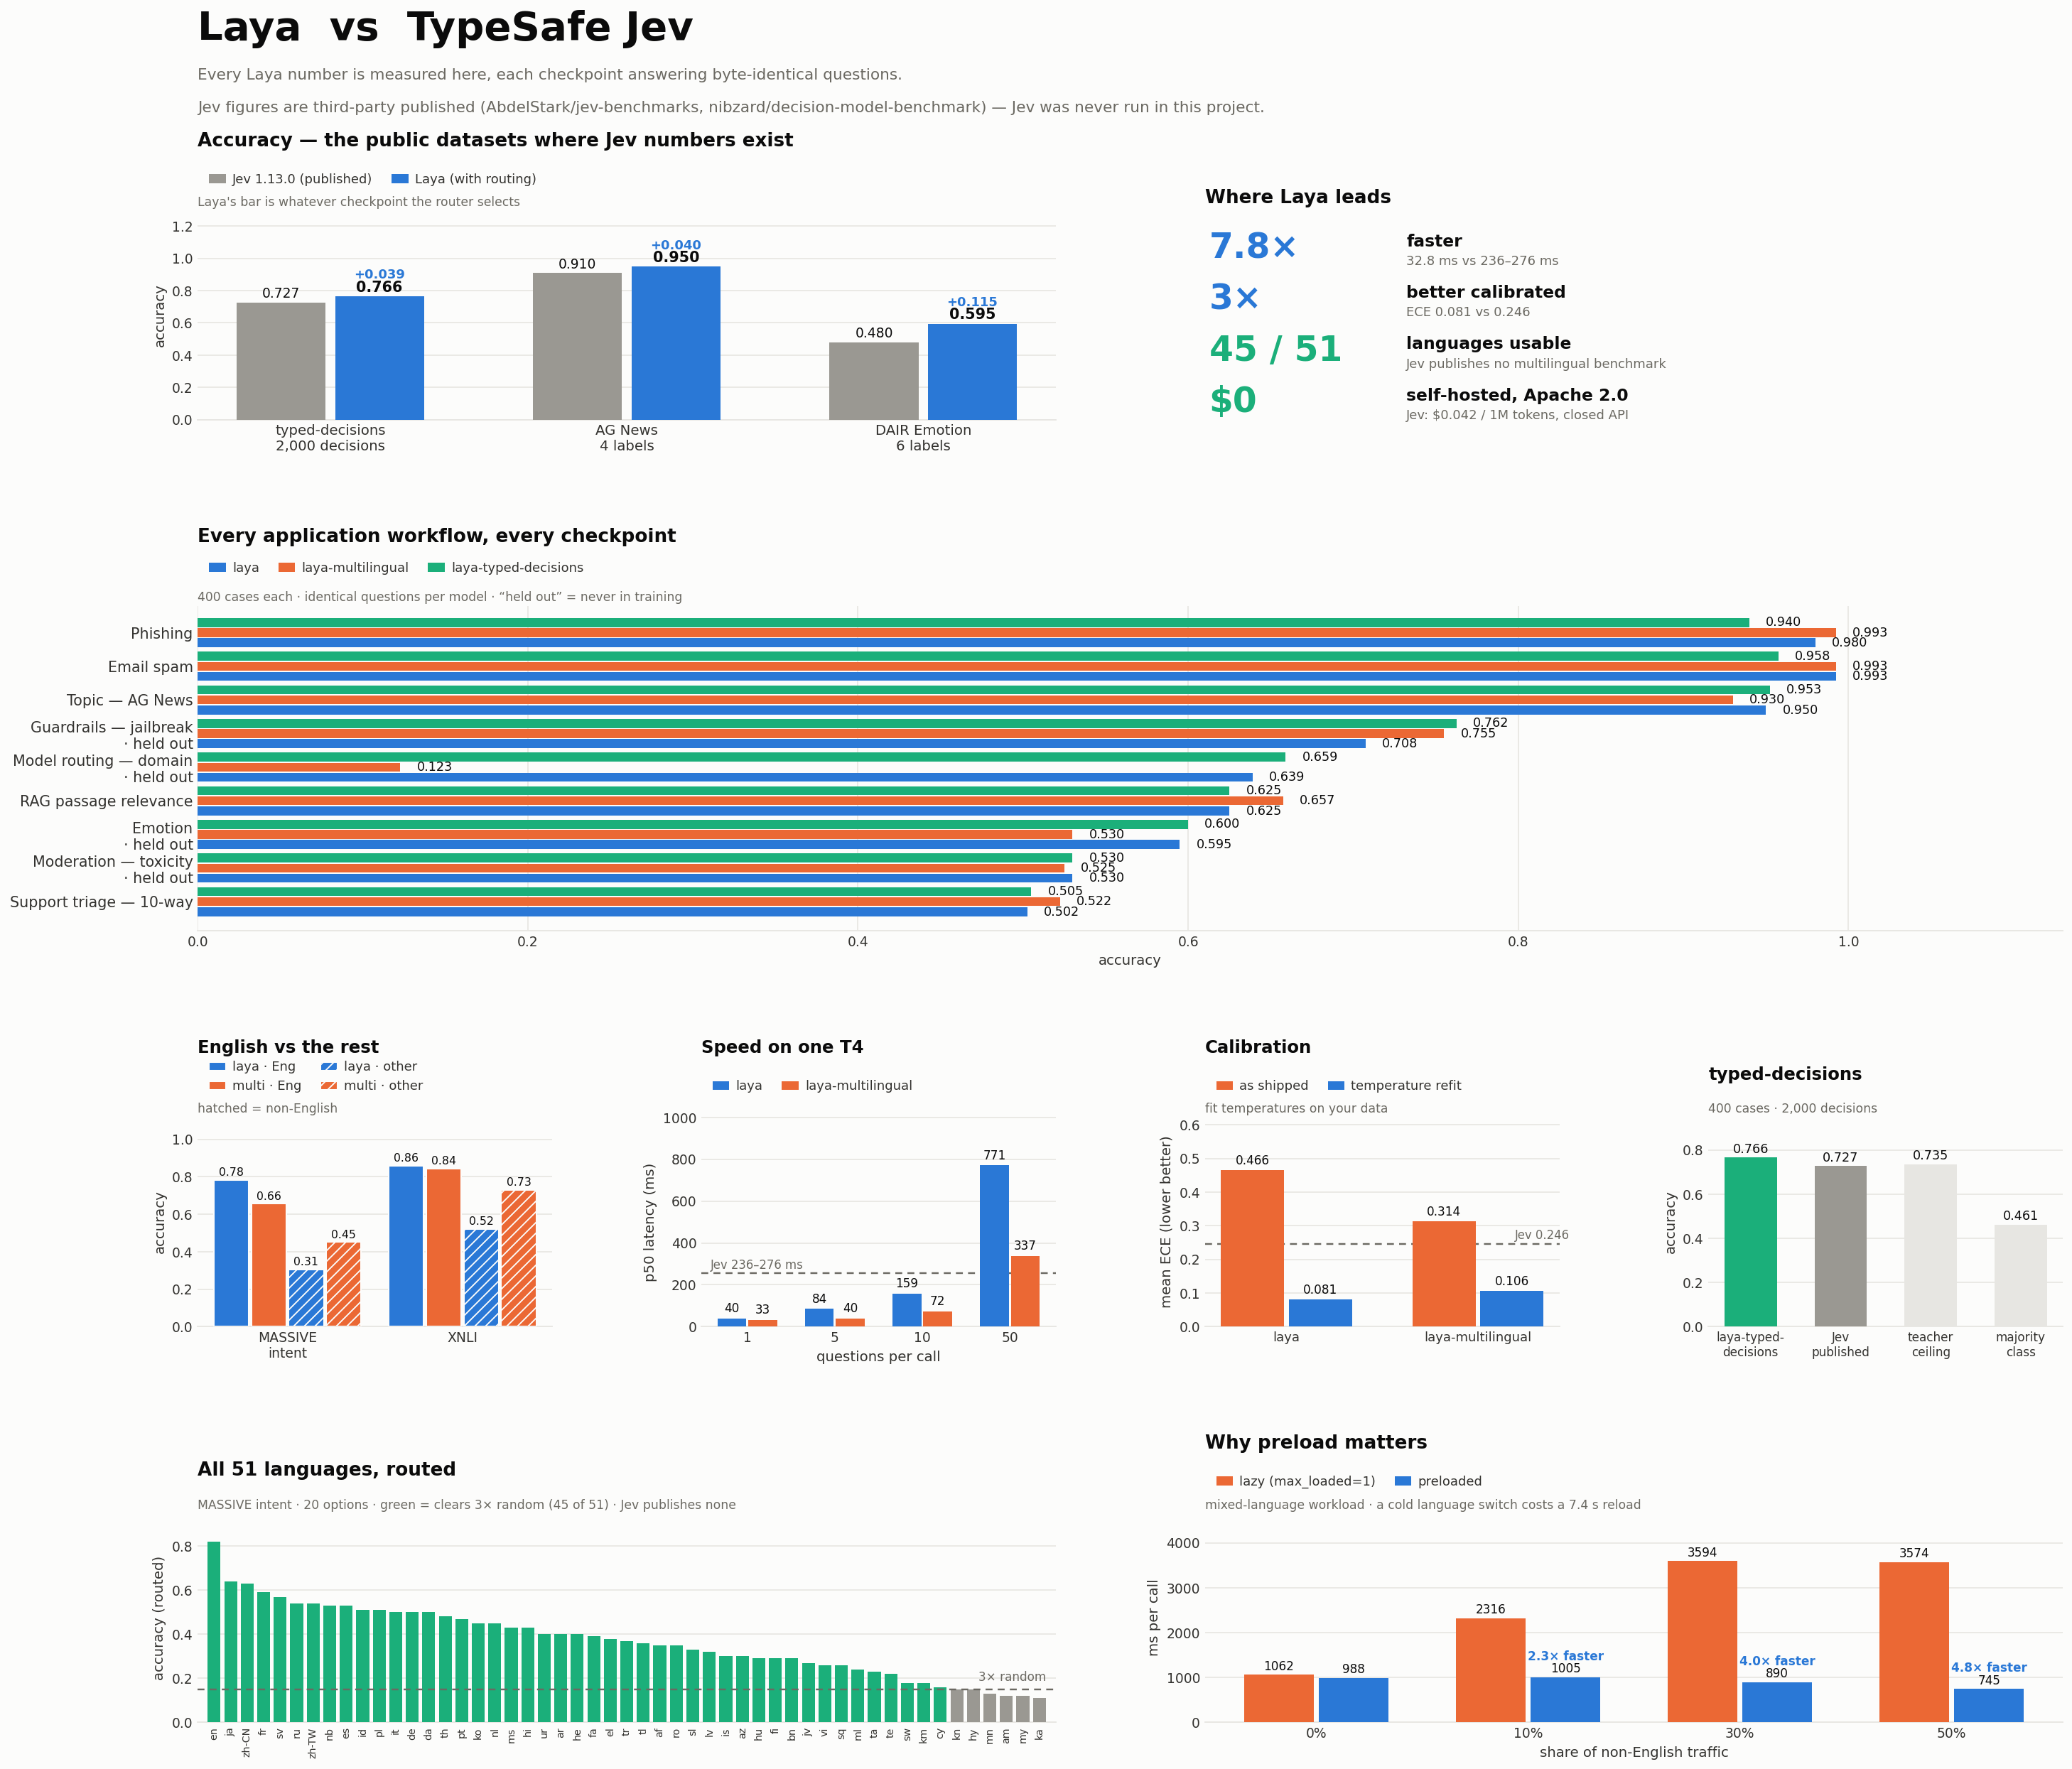
Take ModernBert, add a fully connected layer with 255 outputs, take a bunch of classification datasets from Huggingface, write the code to have the datasets fit the jev format on these 255 outputs, do supervised fine tuning on the datasets with that format. then use a confidence loss of some kind
Comment · 21 days ago
Laya is just ModernBert fine-tuned. It's still a language model (just a bidirectional one). Let's call it what it is instead of this weird Decision Model mysticism.
Comment · 21 days ago
Jev and decision models are *a derivative* of a pretrained LLM trunk, and one that's super easy to build once you have an LLM. Put a single step fully connected NN on the transformer, create a training dataset for it, add fancy but bread and butter multi step decision RL, nothing crazy.

*They have zero moat* against established AI companies, as the recent copies show, and will do worse than frontier labs.*

Comment · 21 days ago
> it'll look a lot more like putting Jev at the center of a much more expensive suite of software

but anyone can do that, that's not their product, Jev is
Live from the official Hacker News API

A modern reader for Hacker News · SvelteKit + Skeleton