

johndough
Joined 9 years ago
Karma
1,828
Submissions
563
Member since
Feb 18
Joined 9 years ago
When Reddit raised its API prices in 2023 in order to make itself more attractive for an IPO, it effectively priced out third-party apps, such as the Apollo reader app. Discussion back then: https://www.reddit.com/r/apolloapp/comments/13ws4w3/had_a_ca...
https://openrouter.ai/stealth/ox-alpha#uptime
https://openrouter.ai/z-ai/glm-5.3#uptime
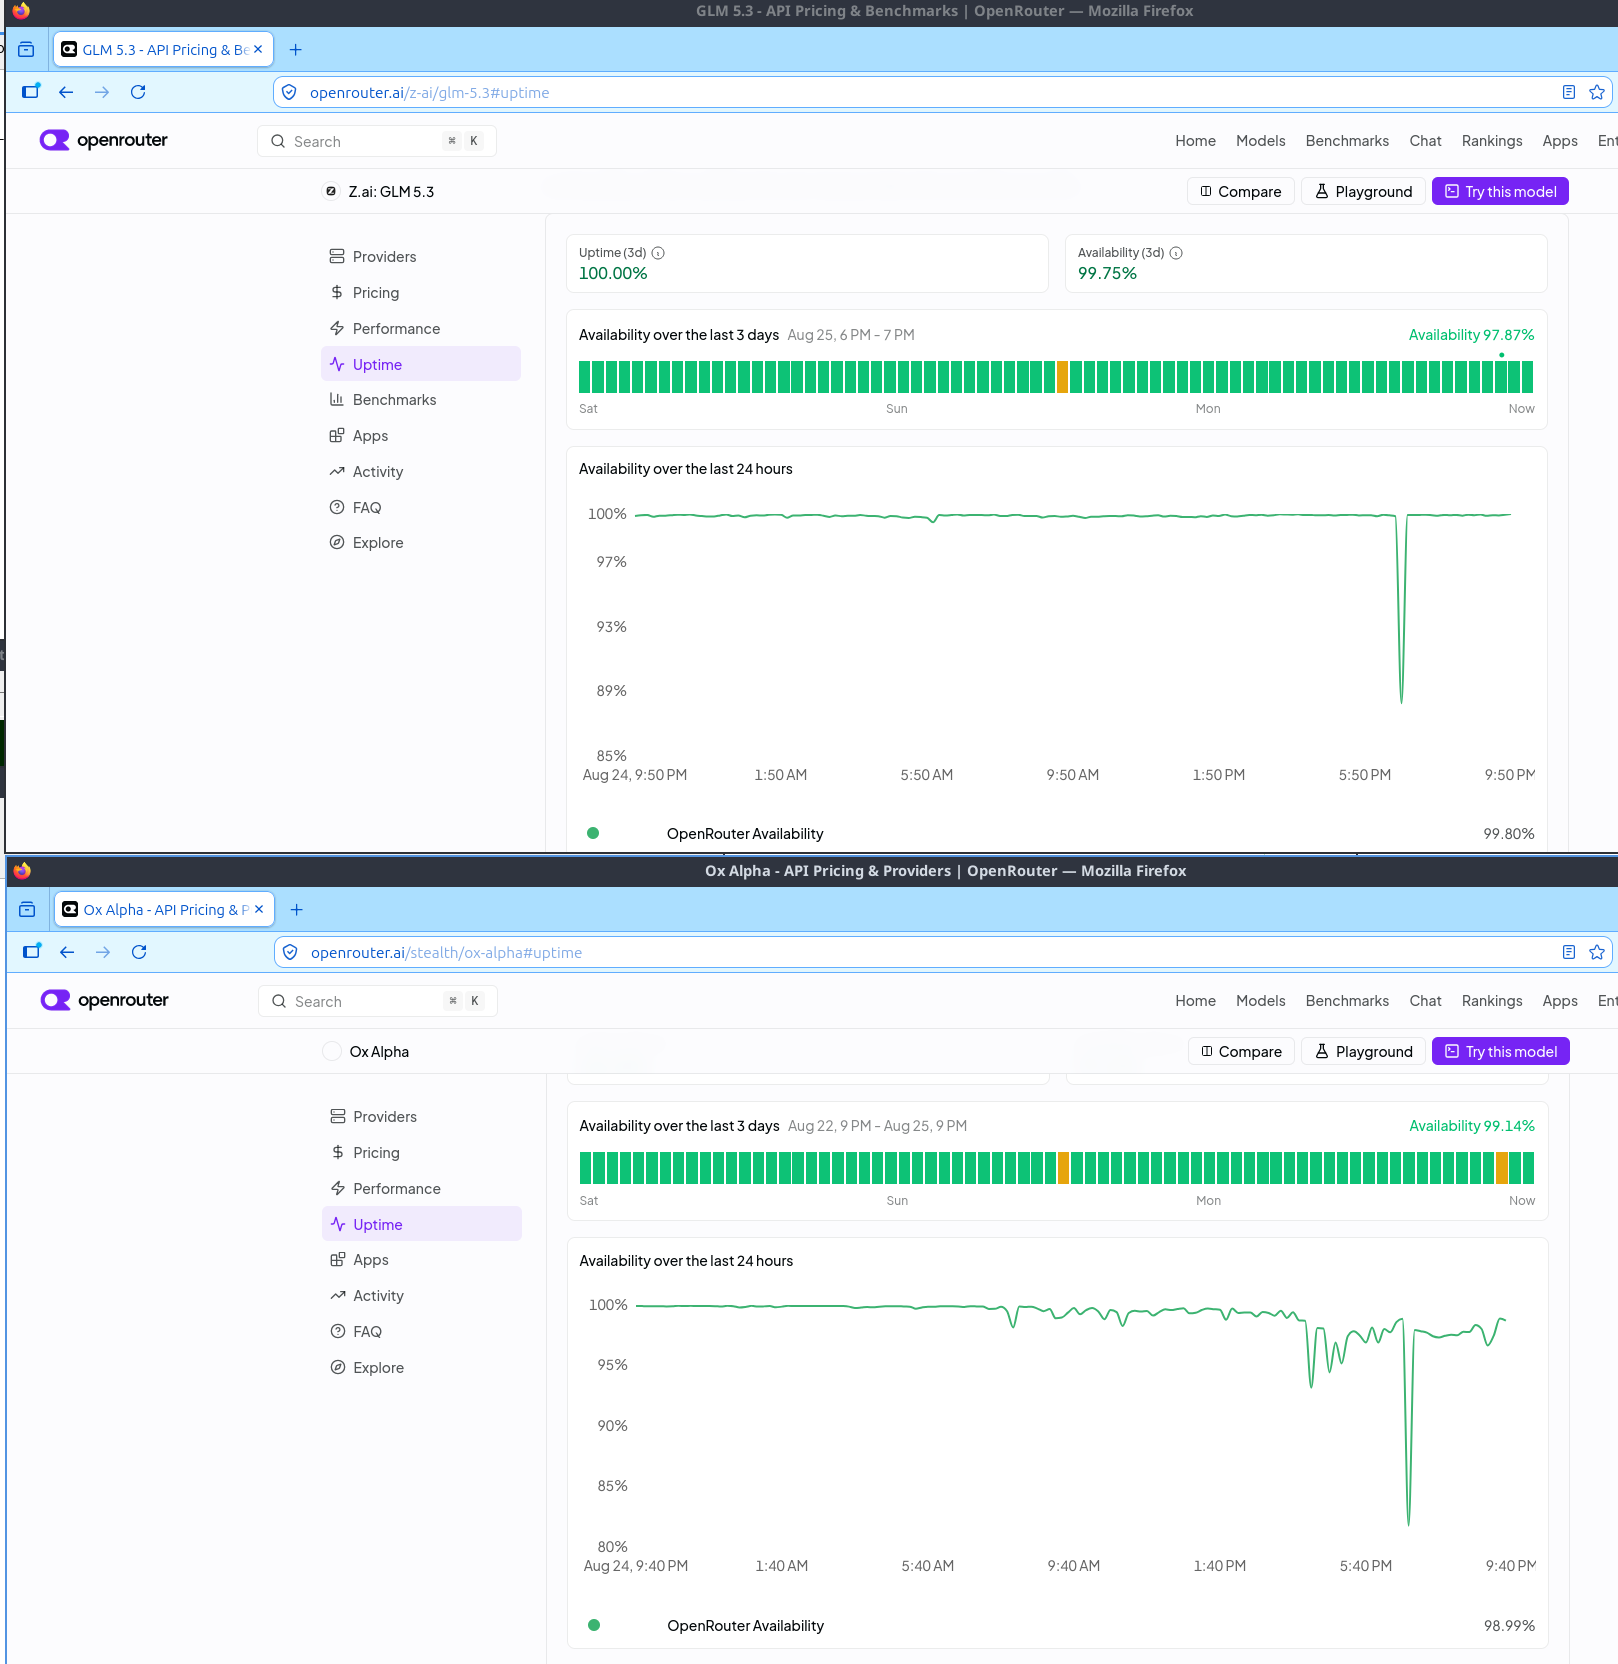
Screenshot of a recent blip: https://files.catbox.moe/haq90y.png
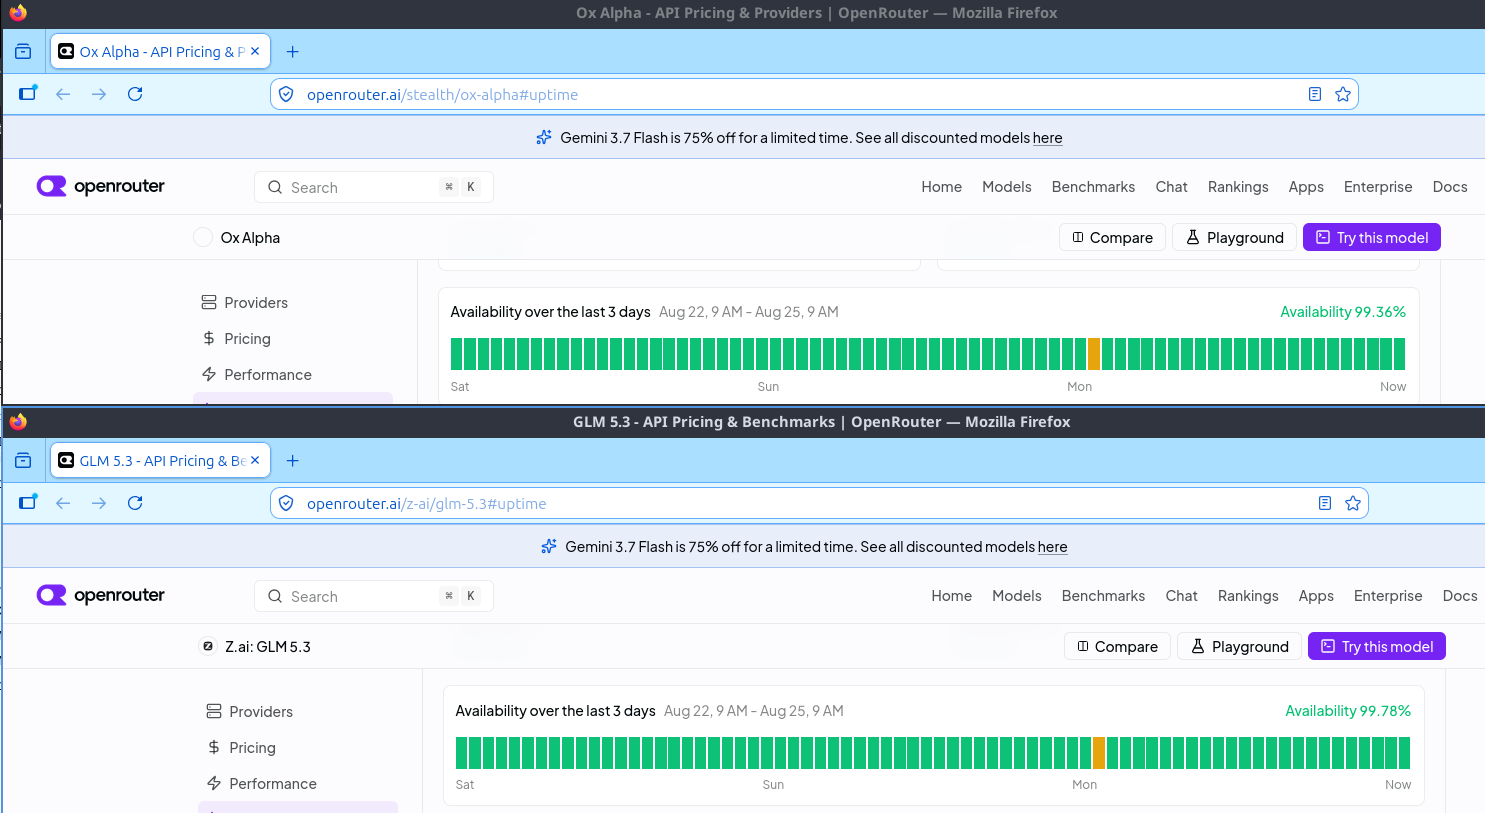
https://files.catbox.moe/k52n6k.png
The upper chart shows the availability of Ox Alpha and the lower chart shows the availability of GLM 5.3 by Z.ai. They had a blip at exactly the same time.
> 1 quadrillion tokens per day on Nous portal
Don't post generated text or AI-edited text. HN is for conversation between humans.
I tried to parse hand-drawn ER diagrams in the past and did not have much success with any model, frontier or otherwise. If you have annotated data, I'd recommend finetuning a recent (dense) VLM, but don't expect 100% accuracy. https://unsloth.ai/docs/basics/vision-fine-tuning
    LLM issues tool call to read high res image ->
    harness sends high res image to server ->
    server downsizes it to 800x800 (blurry) ->
    LLM issues bash command (e.g. `convert`) to crop a small subimage (e.g. 600x600) from the high res image ->
    LLM issues tool call to read subimage ->
    harness sends subimage to server ->
server does not resize the subimage because it is small already, so it is not blurry when finally ingested by the LLM Nevertheless, as a component, we will undoubtedly implement multimodal support — and we are already doing so. We plan to develop relevant models, ensuring that versions like V4 and subsequent iterations will natively support multimodal functionality.
    Achieving excellence in AI training does not require a global model or even multimodal approaches—by narrowing the scope of AI training and eliminating multimodality, certain tasks may remain unachievable without compromising the algorithm's validity.

    Multimodal approaches ultimately need to be implemented.
I am using a stripped-down minimal version of it which I uploaded here, since I am not a fan of huge dependency trees: https://github.com/99991/simple-pp-doclayoutv3
Another recent model for this task is Unlimited-OCR: https://github.com/baidu/Unlimited-OCR
My visit to your website went like this:
1. Visit models page
2. Try to find GLM-5.3-Flash (which is among the ~5 models that 90% of people currently care about)
3. Give up scrolling (which would have taken OVER 50 SCROLLS!!!) and use Ctrl + F
4. Try to find input/output/cached price
5. Scroll all the way up to find out which column is what
6. Notice that output price is cut off
7. Notice that the scroll bar is over 100 scrolls further down the page
8. Use Shift + Wheel to scroll horizontally (most visitors probably won't know this trick)
9. Notice that cached price is missing
10. Conclude that this is probably not a serious offering and bounce
There are probably more issues later on, but this is how far I got.
I would suggest you to:
- Deslopify all pages that a user may visit before conversion
- List important models first (see OpenRouter rankings)
- Move the most important information (model name/input/output/cached price) to the left
- Disaggregate the prices per provider (maybe subtables per model? not sure)
- Measure cache hit rate and compute effective price per provider (see OpenRouter)
(- Optional: Fix the broken link on your HN profile page. Currently, the only way to get from this comment to your website is a search engine.)