emmericp
Joined 9 years ago
Karma
393
Submissions
70
Member since
Nov 19
Artisanal handcrafted network card drivers:
https://github.com/emmericp/ixy
View on Hacker NewsJoined 9 years ago
The other Wiktionary example of "freie Krankenversorgung" sounds wrong to be, but it seems to be used rarely in some more formal or legal contexts, no one would say it like this in a casual conversation. Google results also show a 4x difference between frei and kostenlos here in favor of kostenlos. But both are low since "Krankenversorgung" is already a very unusual word. I suspect many of those uses might be bad translations from English.
[1] https://www.researchgate.net/publication/390635826_Structura...
I'm not enough of a specification lawyer to say that this is definitely true, but the reasoning and example given there seems sound to me.
[1] https://devblogs.microsoft.com/oldnewthing/20140627-00/?p=63...
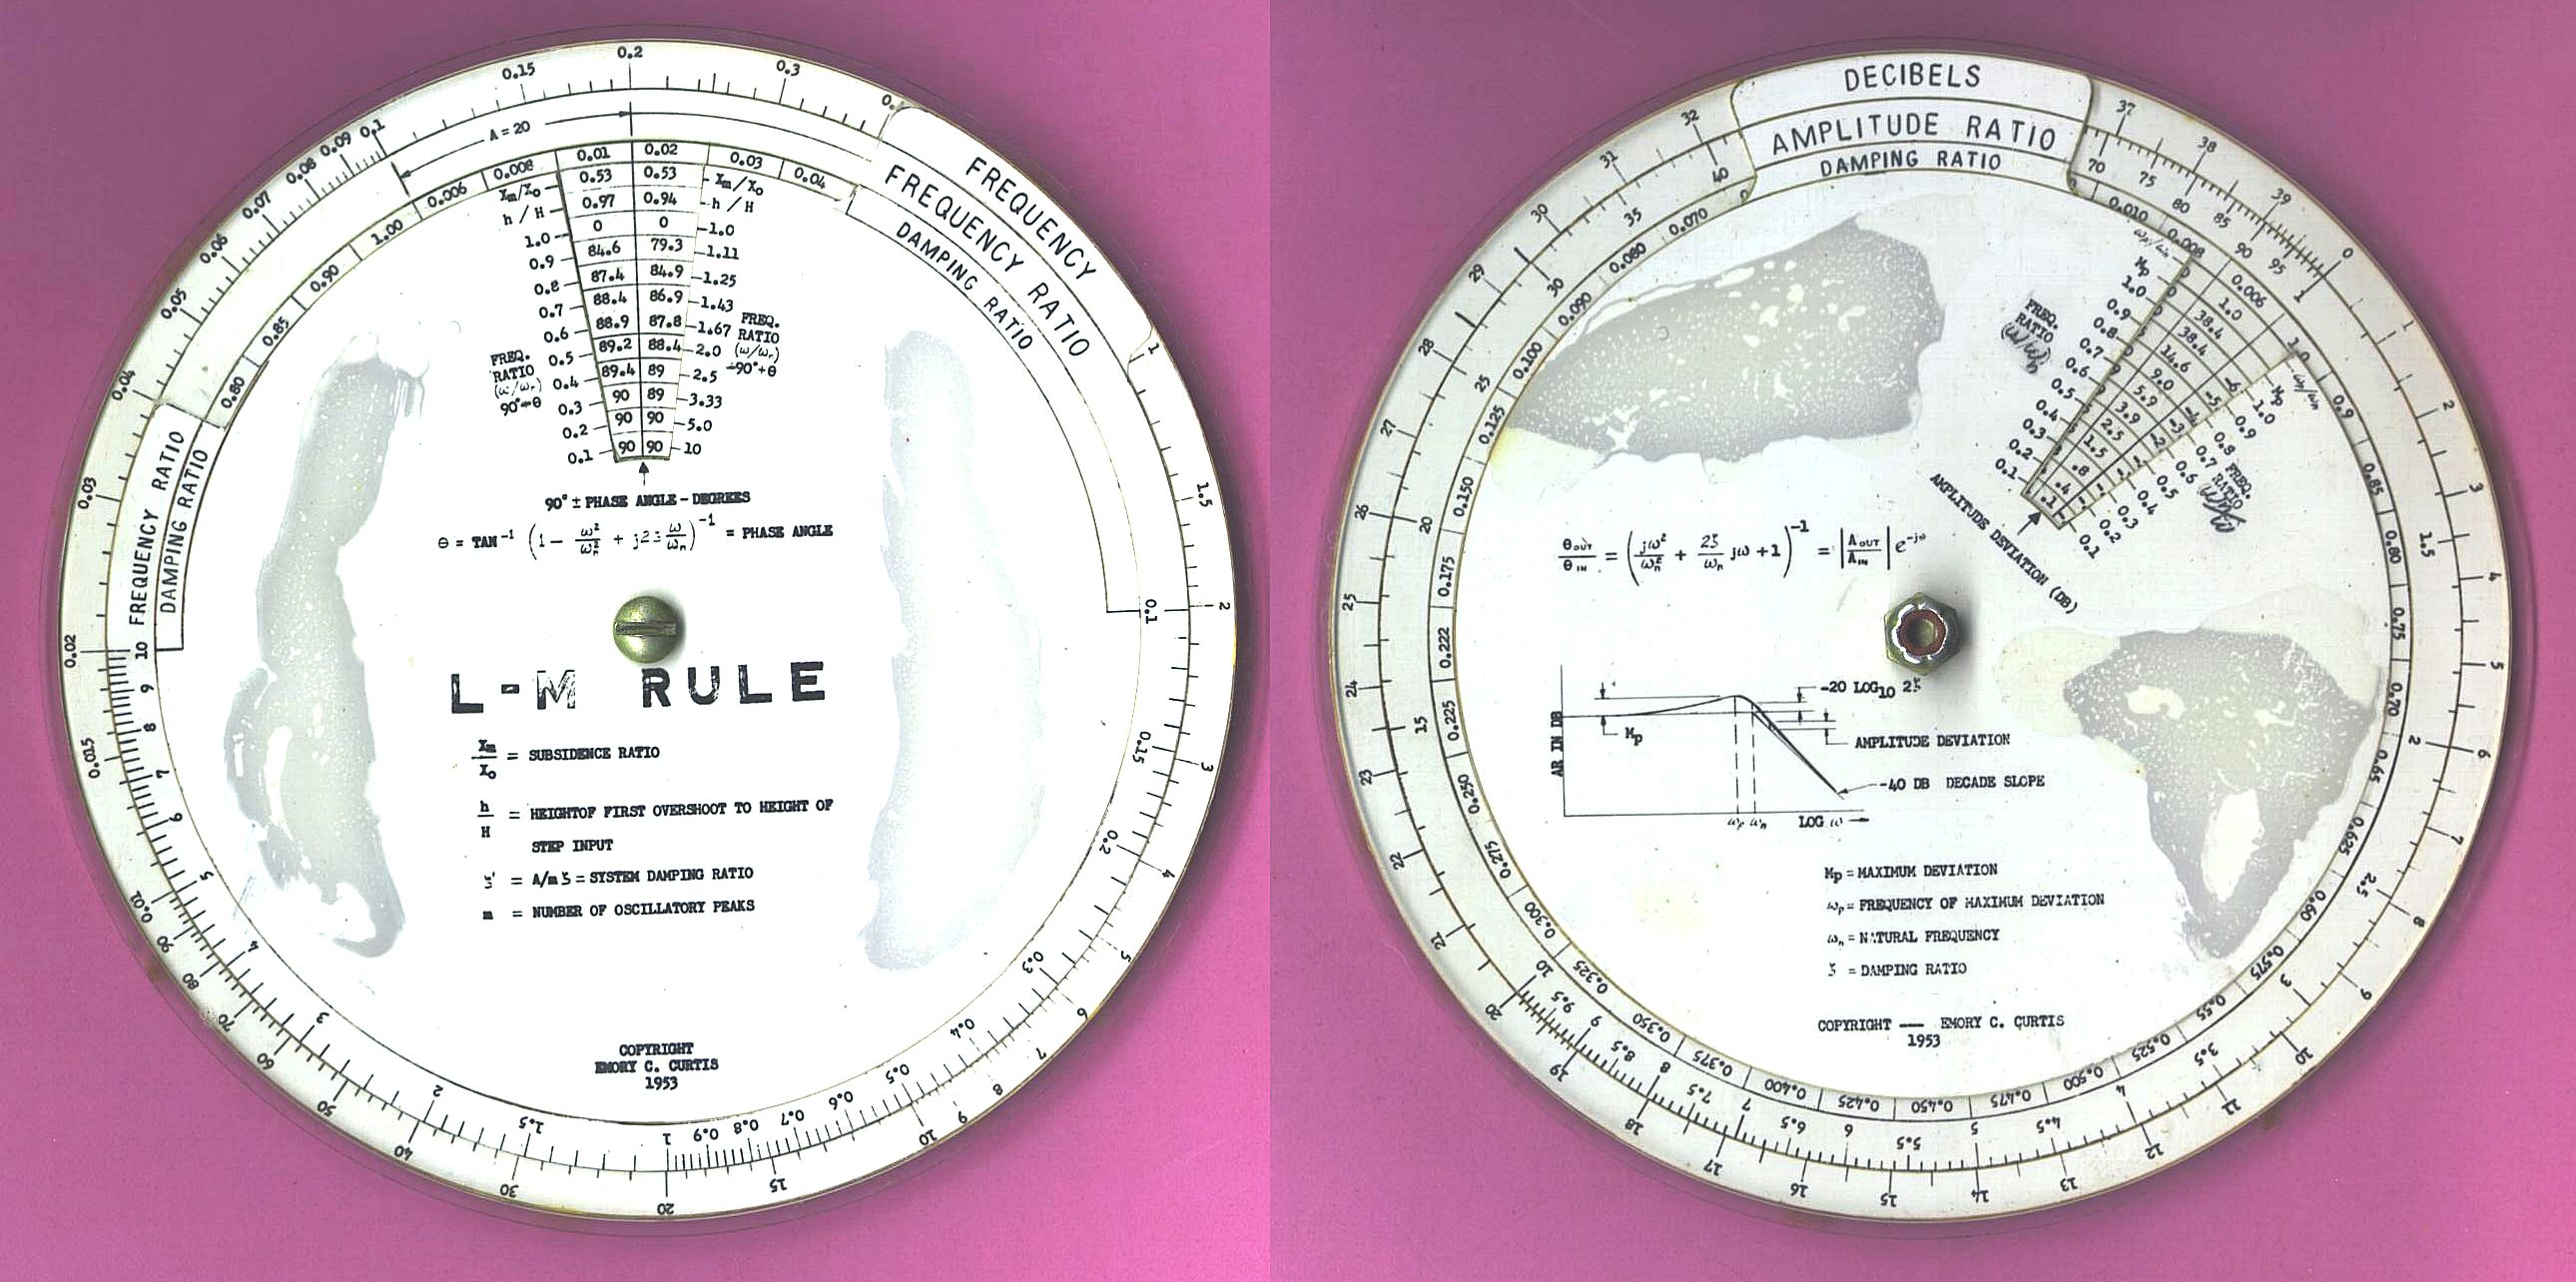
Fun to see this site show up on HN :)
[0] https://sliderulemuseum.com/Circular/Curtis_L-M_FrequencyRes...
Published terrible code is far better than unpublished code.
We've got some graphs [0] comparing throughput and long-tail latency for the various Java GCs available in OpenJDK 12. Shenandoah's worst case pause time was ~45µs which is the same as disabling the GC (Epsilon GC) which is pretty impressive. Overall performance did suffer under Shenandoah a little bit back then, though. However, I've heard that this improved recently.
[0] https://github.com/ixy-languages/ixy-languages/blob/master/J...
If you want empiricism try academic papers instead of mailing lists ;) Some numbers: most critical bugs in the Linux kernel are due to memory safety: 40 out of 65 bugs allowing for code execution found in Linux in 2017 could have been prevented by using a memory-safe language [0]. The paper is about Go, but the same logic applies for Rust. Fun fact: 39 out of these 40 bugs were in drivers [1], so I think starting with drivers in Rust is a good idea.
[0] https://www.usenix.org/conference/osdi18/presentation/cutler (really good read!)
[1] https://arxiv.org/pdf/1909.06344.pdf (disclaimer: I'm a co-author of that paper)
The scaling model of the hardware is rather simple: hash over packet headers and assign a queue based on this. And each queue should be pinned to a core by pinning the interrupts, so you got easy flow-level scaling. That's called RSS. It's simple and effective. What it means is: the hardware decides which core handles which flow. I wonder why the article doesn't mention RSS at all?
Now the socket API works in a different way: your application decides which core handles which socket and hence which flow. So you get cache misses if you don't tak into account how the hardware is hashing your flows. That's bad. So you can do some work-arounds by using flow director to explicitly redirect flows to cores that handle things but that's just not really an elegant solution (and the flow director lookup tables are small-ish).
I didn't follow kernel development regarding this recently, but there should be some APIs to get a mapping from a connection tuple to the core it gets hashed to on RX (hash function should be standardized to Toeplitz IIRC, the exact details on which fields and how they are put into the function are somewhat hardware- and driver-specific but usually configurable). So you'd need to take this information into account when scheduling your connections to cores. If you do that you don't get any cache misses and don't need to rely on the limited capabilities of explicit per-flow steering.
Note that this problem will mostly go away once TAPS finally replaces BSD sockets :)
Lesson 2: Avoid using RAID controllers except for the most simple "pass through" mode.
Lesson 3: XFS+Ceph never really worked out. BlueStore solved so many problems by just removing the XFS dependency for the actual data. Recommended reading: https://www.pdl.cmu.edu/PDL-FTP/Storage/ceph-exp-sosp19.pdf
ceph-volume finally fully removed dependency on file systems. Yeah the LVM-mess is sometimes annoying and early version of ceph-volume had many problems, but nowadays I wouldn't want ceph-disk back.
Sure, there's the rare case of a connection moving to a different L3/4 flow identifier causing a cache miss, but that's not something that happens often enough to be a relevant bottleneck.
I'm not sure about the implementation details of GSO and TSO in Linux. But I know a thing or two about the hardware: the Intel Niantic/82599 NICs support UDP transmit segmentation offloading, I've checked the datasheet real quick and it says "Note that current UDP segmentation offload is not supported by any standard OS."
Not sure if this is just an outdated comment in a 10 year old datasheet or if there's some performance to be gained by using this UDP segmentation offload for quick.
Edit: Should have clicked on the link in the article [1] before posting here, UDP segementation offloading is coming to lots of NIC drivers in 5.5.
Always interesting how the hardware often supports way more features than the drivers expose and you suddenly get new hardware features on a 10+ year old NIC model :) (Similar story with IPsec offloading on the Niantic/82599)
I disagree; TCP timestamps are awesome. Linux enables these by defaults.
Quick search gives me some measurements from 2012 [1] that indicate that TCP timestamps are enabled on 83% of the top 100k web hosts.
You can afford to waste 12 bytes; the bottleneck isn't these 12 bytes but how well you get congestion control to work. And congestion control relies on getting an accurate estimate of the round-trip time
[1] https://link.springer.com/chapter/10.1007/978-3-642-36516-4_... (paywall)
Edit: typo
Edit: Also, just because 83% of web hosts having it enabled does not imply that it is a good idea to do so in general. They could just all be running the linux defaults and these could be just wrong