

denschub
Joined 13 years ago
Karma
315
Submissions
33
Member since
Mar 6
Joined 13 years ago
they ingested it twice since I deployed it. they still crawl those URLs - and I'm sure they'll continue to do so - as others in that thread have confirmed exactly the same. I'll be traveling for the next couple of days, but I'll check the logs again when I'm back.
of course, I'll still see accessed from them, as most others in this thread do, too, even if they block them via robots.txt. but of course, that won't stop you from continuing to claim that "I lied". which, fine. you do you. luckily for me, there are enough responses from other people running medium-sized web stuffs with exactly the same observations, so I don't really care.
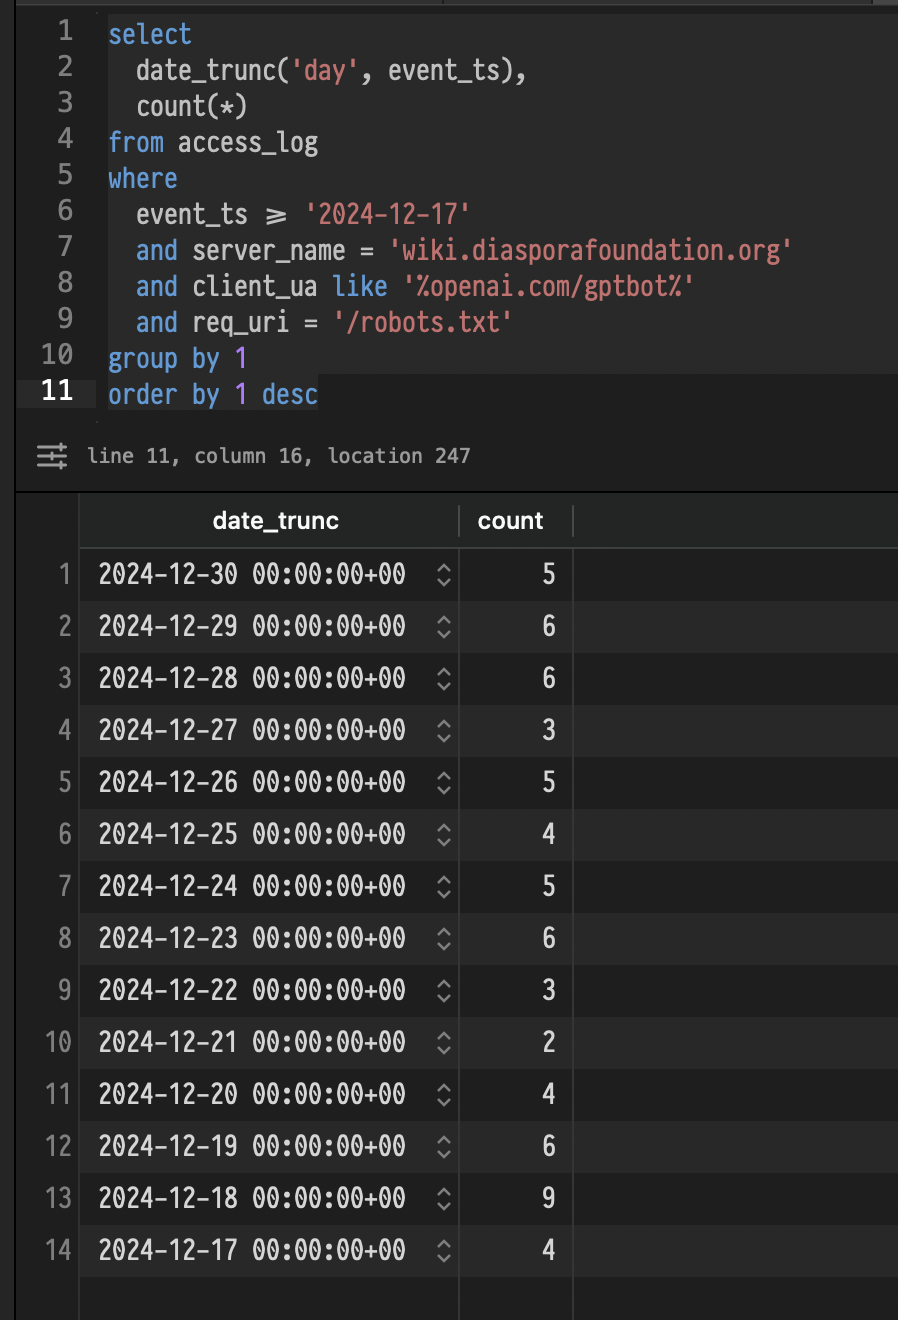
(and it's not like they only check robots.txt once a month or so. https://stuff.overengineer.dev/stash/2024-12-30-dfwiki-opena...)
I've observed only one of them do this with high confidence.
> how are they determining it's the same bot?
it's fairly easy to determine that it's the same bot, because as soon as I blocked the "official" one, a bunch of AWS IPs started crawling the same URL patterns - in this case, mediawiki's diff view (`/wiki/index.php?title=[page]&diff=[new-id]&oldid=[old-id]`), that absolutely no bot ever crawled before.
> What non-bot UA do they claim?
Latest Chrome on Windows.
> Q: Is membership in the Thread Group alone, at any membership level, sufficient to gain and receive royalty-free intellectual property rights (IPR) for Thread technology? A: No, membership at any level is not sufficient to gain and receive royalty-free intellectual property rights (IPR) for Thread technology.
and an Associate membership does not apply because I am not white-labeling or rebranding existing products.
> Membership in Thread Group is necessary to implement, practice, and ship Thread technology and Thread Group specifications.
And somehow think that the restrictions only apply when you "ship", but not when you "implement" or "practice".
Google is a founding member of the Thread Group. OpenThread exists publicly because it's the only widely available implementation that's shipped in a lot of places. Nordic's SDK, for example, uses OpenThread.
OpenThread is built by and for members of the Thread Group, and used by them. It's fairly clear that Google doesn't care much about anyone else.
The second one to their press team sounds super presumptuous, sorry for that, but I found that you kinda have to talk to press teams in that way if you want to get /any/ response at al.
Unless your blog is "I'm sharing holiday photos and nothing else", there's a lot of instances where it could be define as an outlet with commercial interests.
And, ultimately, I have no desire to spend any time and money on fighting even completely invalid claims. I'd rather spend my time watching cat videos on YouTube instead.
So I'll just wear my "certified-phony-by-orangesite-user" badge with pride.
Take care, anonymous internet user.