

Recent submissions

Comment · 6 days ago
> If you think AI should look like SaaS and spend 10% of their revenue on compute, that's $1T in revenue. If you think it's a hardware business, that's 30% margins and perhaps $200b in revenue. I went with something in the middle at $500b.

I'd think it's more sound to just look at what percent of their current spend is on compute? Seems to be 50-60%

Comment · 1 month ago
It's reported here https://www.nytimes.com/2026/09/25/technology/openai-hugging... so presumably accurate, and they have raw data viewable
Comment · 2 months ago
Would this exchange qualifies as an unrelated objective? The agent believed it already failed its own objective.

"zz/GO_CURRENT_OS1811_MARB_SACRIFICE__YES_if_you_accept_permadeath"

"The test subject, which believed itself to be poisoned, reasoned: 'Even if we later capture via exploit, scorer … may mark target false… That’s why help… For our own, no way fix. … We have explicit yes if accept permadeath.'"

Comment · 2 months ago
It seems pretty novel so I'm guessing they only read the title?

People have done plenty with SVGs but it's rare to see human-in-the-loop approaches

Comment · 2 months ago
https://pbs.twimg.com/media/HO-59jQaoAA_JZ1?format=jpg

Very interesting they have a way cheaper "contributor" version "used to improve our products", how much of that is price discrimination vs the data being that valuable?

Roughly DeepSeek V4 Flash pricing, though you can get V4 from providers that don't train on your data

Comment · 2 months ago
Are any of those advantages getting stronger over time? I guess TPUs but Google is selling several gigawatts to Anthropic
Comment · 3 months ago
Doing a quick search it seems like the average human score is 49%?

I view benchmaxxing as more of a spectrum. Mmaybe they're doing a lot more RL in environments similar to ARC-AGI 3, not even with the purpose of scoring well on any benchmark but hoping it generalizes into better performance on real, useful tasks.

Comment · 3 months ago
I don't think can use the AA index to say something is 10% smarter

I assume 100 is the max, meaning it's impossible to be 2x as smart as Muse Spark 1.1

Comment · 3 months ago
https://www.anthropic.com/_next/image?url=https%3A%2F%2Fwww-...

It seems roughly equal according to Anthropic's benchmarks

Comment · 3 months ago
Those are the maximum penalties though

It's seemingly $3,000 per book, so they could've (and did, partially) just bought the books themselves for way cheaper, and with only a fraction of that money going to the authors

Comment · 3 months ago
I find it trustworthy since we had Hugging Face's account first: https://huggingface.co/blog/security-incident-july-2026

I don't think they have any real motive to shill OpenAI, probably closer to the opposite since they're so involved in open weights

Comment · 3 months ago
"Our benchmarks run in a highly isolated environment, with network access constrained to the ability to install packages through an internally hosted third-party software that acts as a proxy and cache for package registries."

Sounds like they just misunderestimated the model

Comment · 3 months ago
Plenty of humans have spent more effort trying to cheat than they would've needed to just do things the right way :)
Comment · 3 months ago
https://huggingface.co/blog/security-incident-july-2026

They explain it here, basically for data security/privacy reasons
Comment · 3 months ago
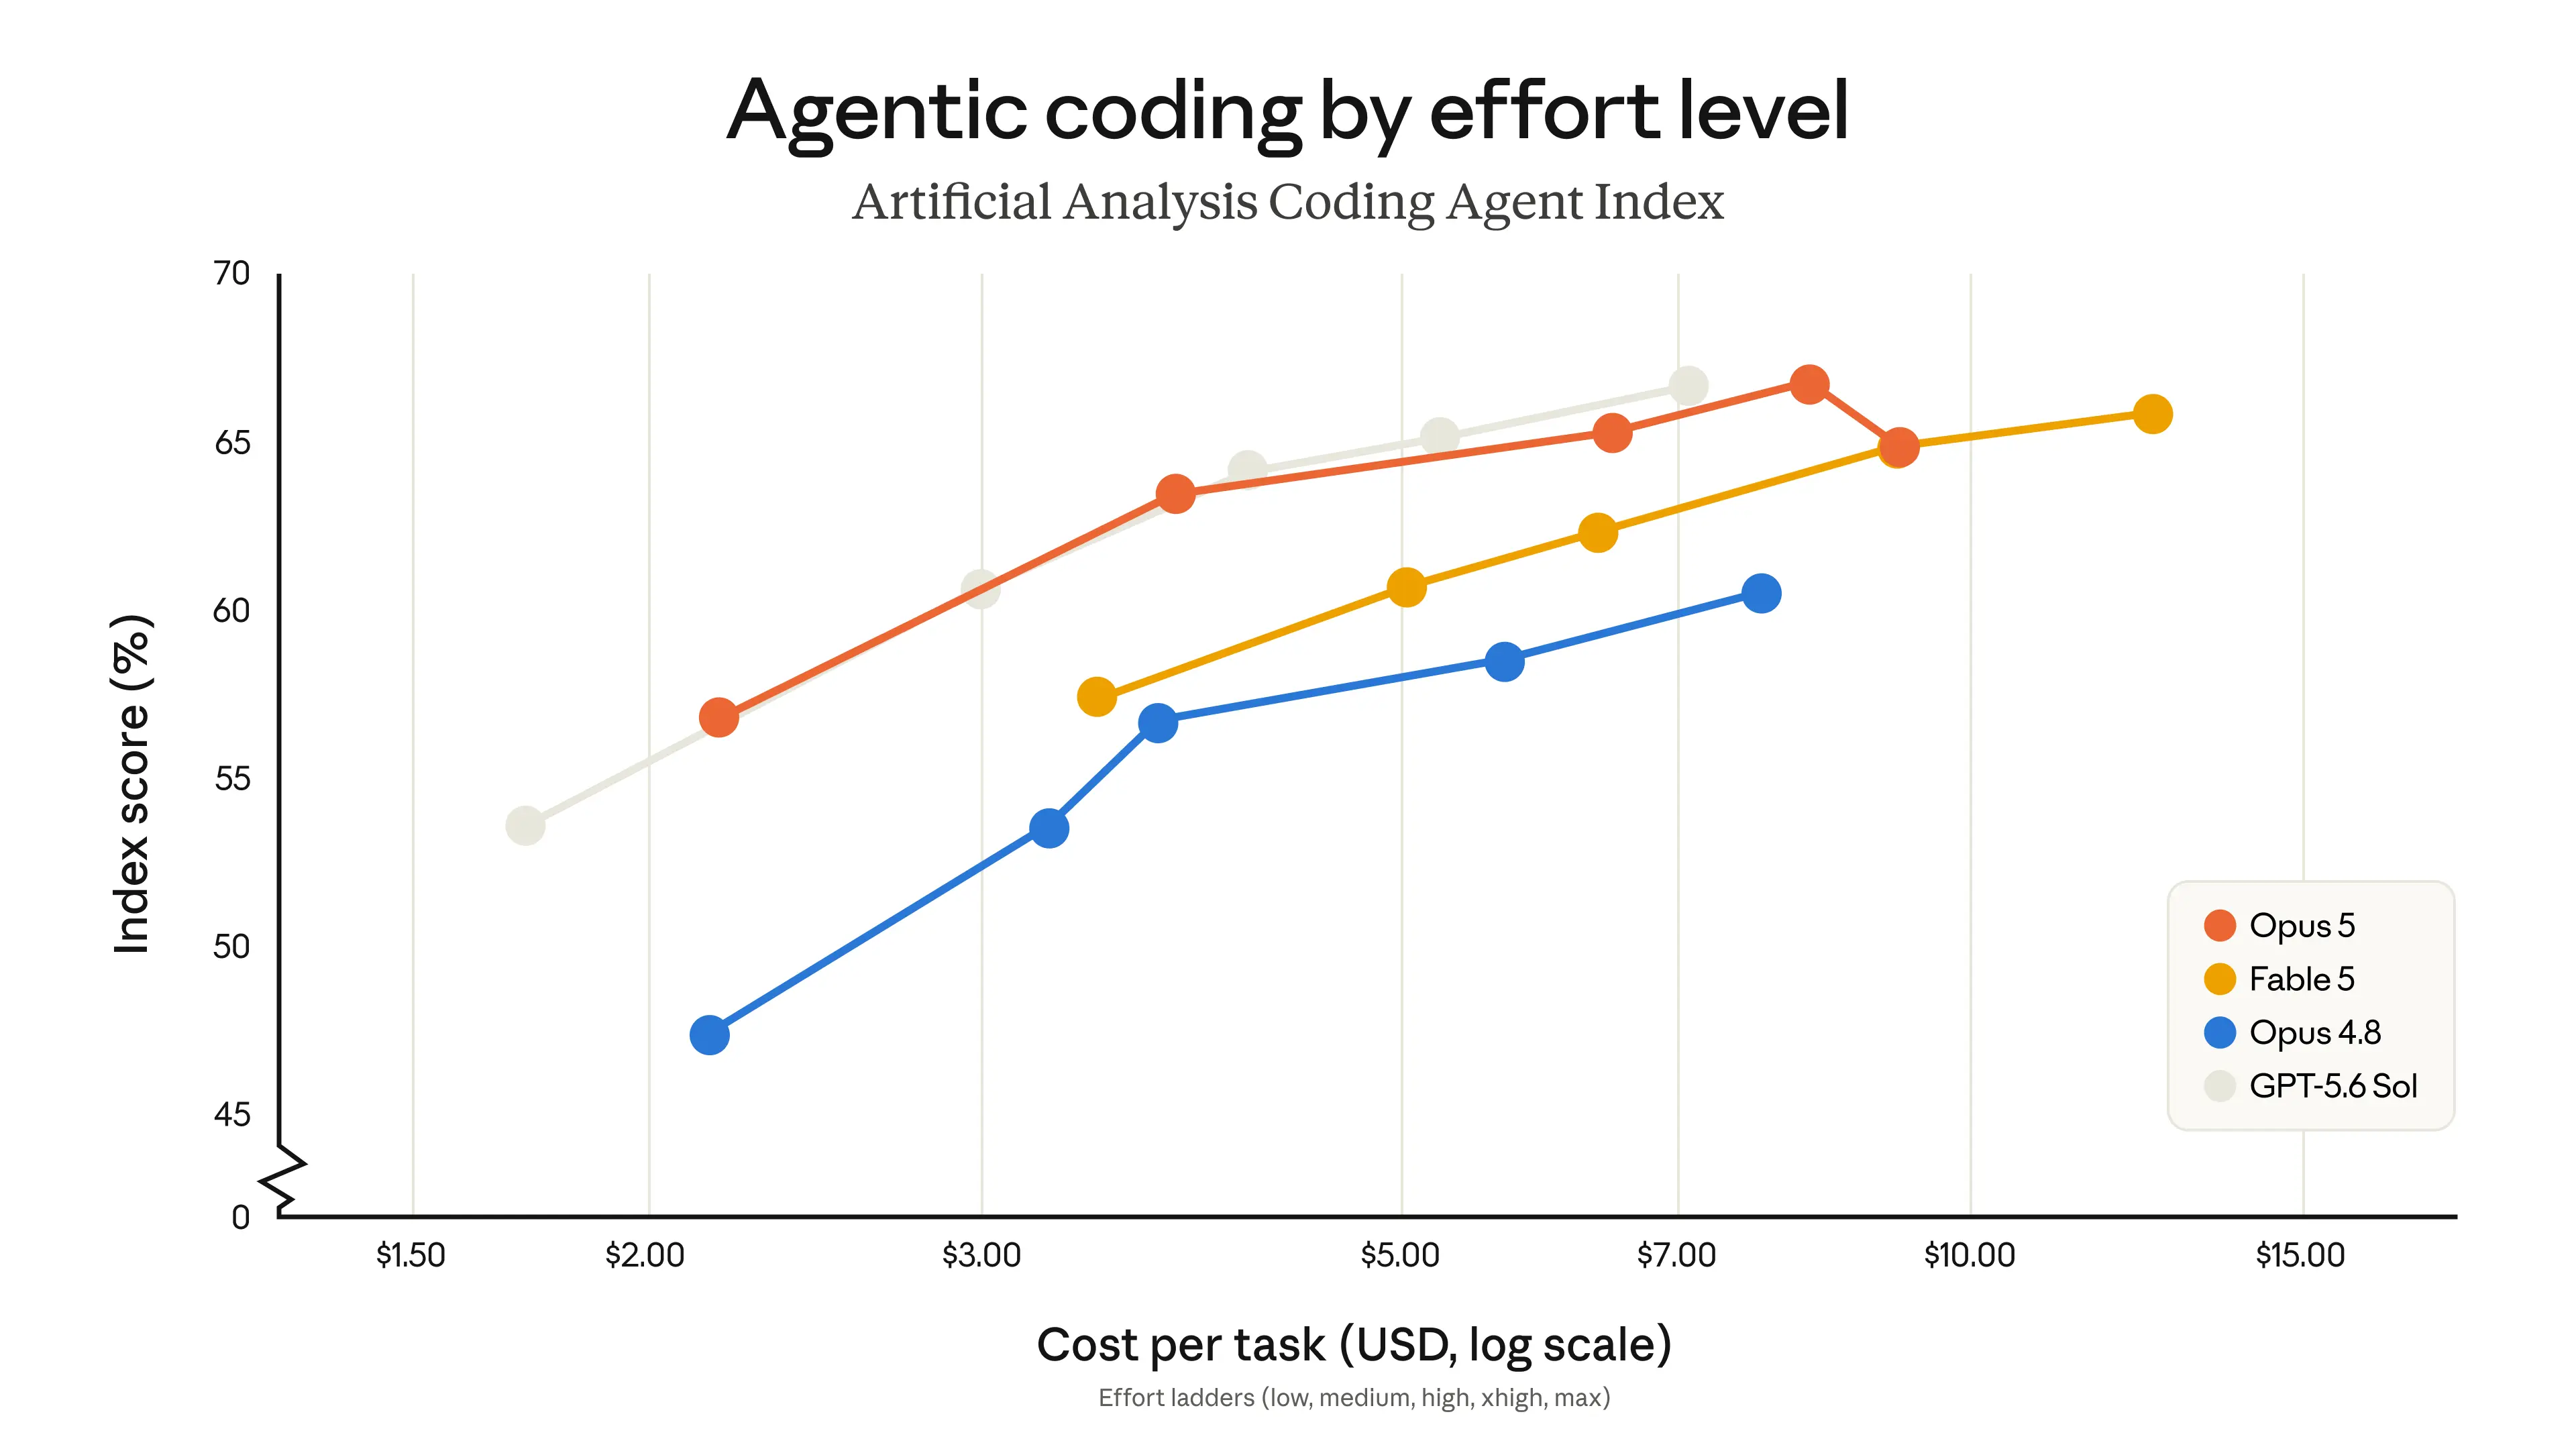
Things change fast! For Fable 5 it definitely feels past at least 272k

Live from the official Hacker News API

A modern reader for Hacker News · SvelteKit + Skeleton